FlashAttention 3 - A Worklog
Hello all. This blog post is about how to implement Flash Attention 3, specifically with CuteDSL, targeting H100 GPUs. The main goal of this work is to create a worklog on incrementally building and adding features to each kernel, to clearly and cleanly understand how we can get to Model FLOPs Utilization(MFU).
Much of this work is inspired by some of the best people whose content I really enjoyed in the GPU kernel optimization and ML performance engineering domain, specifically Simon, Aleksa Gordic, Kapil Sharma, and Hamza for their similar worklogs, which made me want to create one like this in the first place. Since this is going to be my take on such a worklog, I wanted to do something not available on the internet, or at least not in the form of a worklog.
- How to Optimize a CUDA Matmul Kernel for cuBLAS-like Performance: a Worklog - Simon Boehm
- Inside NVIDIA GPUs: Anatomy of high performance matmul kernels - Aleksa Gordić
- Learn CUTLASS the hard way! - Kapil Sharma
- Worklog: Optimising GEMM on NVIDIA H100 for cuBLAS-like Performance (WIP) - Hamza
At present, most ML/AI architectures depend on two basic primitives: GEMM and Attention. I’m taking Attention(specifically Flash Attention) and exploring its kernel design and how to push it toward MFU. Below is the rough plan.
Flash Attention 3(FA3) Worklog:
- Attention math
- Online softmax
- GPU memory and compute hierarchy
- Tiling
- FA2
- CuTe DSL fundamentals and primitives
- K1: naive attention
- K2: tiled softmax
- K3: TMA loads and an mbarrier pipeline
- K4: WGMMA
- K5: warp specialization
- K6: ping-pong scheduling
- K7: FP8
- K8: FP8 + incoherent processing
The plan is to follow the above as one section each. Throughout this worklog, I’ll provide good intuition along with the details on how things work or what we need to make them work. Since each of these can be its own topic, I’ll also add separate notes for many of them, which you can refer to if you want to go in-depth.
I sincerely thank all the many people who planted this idea in me. I hope this will be helpful for anyone who wants to understand FlashAttention 3 (FA3) from first principles. All the code will be made available here: FlashAttention3
I’ve made sure there aren’t any conceptual mistakes. If you find any, please let me know and I’m happy to correct them and make this useful for everyone. If you’re in this domain, feel free to ping me; I’m happy to collaborate on projects around GPU kernels and ML perf engineering.
I’ll add references along each section, instead of tagging them at the end. I’m assuming basic ML/AI and GPU knowledge to get the best out of this blog. All the analysis will be on H100 SXM GPUs, since FA3 was targeted at the Hopper architecture and aims to squeeze out its full utilization through Hopper-specific features like TMA, WGMMA, asynchronous operations, and FP8 support. One point worth mentioning here: there isn’t a huge algorithmic difference between FA2 and FA3, but a lot of engineering work went into FA3 to take advantage of Hopper. FA2 reached around 70% of theoretical max FLOPS on Ampere (A100) but didn’t exploit Hopper-specific features, while FA3 reaches around 75% on H100 in FP16, and with FP8 it gets close to 1.2 PFLOPS with 2.6x smaller numerical error than baseline FP8 attention. More on this in the upcoming sections.
Also, you’ll come across a lot of acronyms throughout this blog. I expand each term on its first use, so if you hit one you’re unsure about, a quick Ctrl+F will take you back to where it was introduced.
That’s it on the intro. Let’s get started.
Reference of FlashAttention-3 Paper - Link
Attention Math
Attention is the core of transformers, and transformers are the core of large language models (LLMs). Transformers consist of two primitives, attention, followed by feed-forward networks (FFNs), surrounded by norms and residual connections. Below is an image that captures this.

Attention gives you the context of what is being referred to and meant in a sentence, and the FFN predicts the next token based on this context. Both are critical to each other and together form the backbone of present-day LLMs.
Now, if we look at attention in more detail, it’s composed of three operations:
\[S = Q K^\top \tag{1}\] \[P = \text{softmax}(S) \quad \text{(along the last dimension)} \tag{2}\] \[O = P V \tag{3}\]Refer to Jay Alammar’s transformers blog if you’re not sure of the attention mechanism and what happens under the hood.
Here, (1) and (3) are matrix multiplications. In GPU terminology, we call them GEMM (General Matrix Multiply), and (2) is a softmax along the last dimension. This matters because softmax was a major bottleneck before, and FlashAttention made algorithmic changes to how it’s computed, while staying numerically exact.
Note: There is a scale factor of \(1/\sqrt{d}\) applied to \(S\), which we’re ignoring here for simplicity. The scale keeps the dot products from growing too large as \(d\) increases, which would otherwise push the softmax into saturated, low-gradient regions. In code, we’ll definitely include it. There is also a causal mask that needs to be applied, to make sure each query attends only to keys prior to it and not after. This is needed for next-token prediction.
The reason for optimizing attention is that materializing the intermediate \(S\) and \(P\) matrices is expensive. Why? Think in terms of dimensions and how much memory we’d need to get this computation done.
Let’s do a simple calculation. Let \(Q\), \(K\), and \(V\) be of shape \((b, s, d)\) → (batch, sequence length, model dim). Then \(S = QK^\top\) has shape \((b, s_1, s_2)\). Now apply softmax. What happens when the sequence length is 1 million and batch size is 1? Assuming FP32 (4 bytes per element):
\[1 \times 10^6 \times 10^6 \times 4 \text{ bytes} = 4 \times 10^{12} \text{ bytes} = 4 \text{ TB}\]And that’s just to materialize one \(S\) matrix. We still need to do the softmax and another matmul on top of that. Attention is also computed many times, since LLMs have hundreds of transformer blocks. Most GPUs don’t have 4 TB of memory, and even if they did, it still wouldn’t be feasible, we need space for intermediate results and bookkeeping too.
This is the major bottleneck FlashAttention addresses. At its core, it does two things: online softmax and tiling. Together, these ensure we never materialize the full \(s \times s\) matrix in GPU memory, while producing the exact same numerical result as if we had. This is what made it possible to train models with longer sequence lengths, which gave us more context and helped LLMs become much more useful.
There are a lot of details in and around this, but we’ll focus on FlashAttention 3 going forward, with all necessary information and intuition along the way for each optimization and topic. With a sense of what attention does and why we need to optimize it, we’ll next talk about online softmax.
A side note:
If you want to understand how LLMs work more clearly, try implementing one. Check out the Stanford CS336 course and follow their assignments, they’re self-contained and really push you to have a clear understanding of all the internals of LLMs. I did it as part of my coursework at NYU, and I’m glad to have taken that course. Highly recommend it.
Also, take a look at this: Transformer block accounting and the below image, think through it to understand the memory and FLOPs counts for a transformer block. This gives you a picture of what it takes to run one transformer block, so you can appreciate all the engineering that’s gone into making it fast and efficient.

Online Softmax
First, let’s revisit softmax and where it’s used.
Given a list of numbers \(\{x_1, x_2, \ldots, x_N\}\), for each element we compute \(e^{x_i} / \sum_j e^{x_j}\) and that produces a new list. Why do we do this? To make sure the new list sums to 1. Softmax is applied as the final step so that the probabilities over all choices add up to one. In the case of attention, we apply softmax to \(QK^\top\). These are the scores given to each key for a given query, and all the scores for a given query must add up to 1. We then use these scores to weight the value matrix through the \(PV\) matmul.
Now, one more important aspect: along which dimension of \(S = QK^\top\) do we apply softmax? The shape of \(S\) is \((b, s_1, s_2)\), where \(s_1\) is the query sequence length and \(s_2\) is the key sequence length. The last dimension is the key’s sequence length, and softmax is applied along this one, so that for each query we get the importance of every key and can extract the context.
With the softmax concept in place, we’ll proceed to online softmax. Here, instead of processing the full list at once, we process it in chunks and rescale the partial results as and when needed. At the end, we get the exact same result as if we had processed the whole list at once. To process in chunks and rescale, we need to keep a few temporary variables for bookkeeping. The reason we want this: our bottleneck is that we can’t hold the full list of numbers in memory, and chunk-by-chunk processing avoids that, at the cost of a little bookkeeping. That’s the gist of online softmax. Now let’s look at the actual math.
The math
Before getting to online softmax, we need to address an overflow issue with exponentials. The largest representable value in float16 (fp16) is 65504. For large \(x\), \(e^x\) overflows this range. To mitigate this, we use a trick known as safe softmax: subtract the max before exponentiating.
\[\frac{e^{x_i}}{\sum_{j=1}^{N} e^{x_j}} = \frac{e^{x_i - m}}{\sum_{j=1}^{N} e^{x_j - m}}, \quad \text{where } m = \max_{j=1}^{N} x_j \tag{4}\]Subtracting \(m\) guarantees \(x_i - m \le 0\), so every exponent is non-positive, which is the safe region for the exponential.
Note: this can make some terms very small. If \(x_i\) is far below the max, \(e^{x_i - m}\) can underflow to 0 in fp16. Unlike overflow, this is harmless: a term that underflows was already negligibly small, so it contributes essentially nothing to the sum or to the final probability. Overflow produces inf and corrupts the whole result, whereas underflow just drops a value that rounds to zero anyway.
3-pass safe softmax
Notation: \(m_i = \max_{j=1}^{i} x_j\) with \(m_0 = -\infty\); \(d_i = \sum_{j=1}^{i} e^{x_j - m_N}\) with \(d_0 = 0\) (\(d_N\) is the safe-softmax denominator); \(a_i\) is the final softmax value.
\[m_i = \max(m_{i-1},\, x_i) \tag{5}\] \[d_i = d_{i-1} + e^{x_i - m_N} \tag{6}\] \[a_i = \frac{e^{x_i - m_N}}{d_N} \tag{7}\] \[\begin{aligned} &\textbf{for } i = 1 \ldots N: \\ &\quad m_i = \max(m_{i-1},\, x_i) \\[6pt] &\textbf{for } i = 1 \ldots N: \\ &\quad d_i = d_{i-1} + e^{x_i - m_N} \\[6pt] &\textbf{for } i = 1 \ldots N: \\ &\quad a_i = \dfrac{e^{x_i - m_N}}{d_N} \end{aligned}\]This algorithm iterates over \([1, N]\) three times. In the context of self-attention, the \(x_i\) are the pre-softmax logits computed by \(QK^\top\). When \(N\) is large, all \(N\) logits don’t fit in memory at once, so we need to break the computation into chunks rather than processing the full row in one shot. That is exactly what online softmax does (the GPU memory hierarchy that makes this necessary is covered in the next section).
From safe softmax to online softmax
If we fuse equations (5), (6), and (7) into a single loop, we reduce the number of global memory passes from 3 to 1. Unfortunately, we cannot fuse (5) and (6) directly, because (6) depends on \(m_N\), which isn’t known until the first loop finishes.
The fix: define a surrogate sequence
\[d_i' := \sum_{j=1}^{i} e^{x_j - m_i} \tag{8}\]as a stand-in for the original \(d_i := \sum_{j=1}^{i} e^{x_j - m_N}\). This removes the dependency on \(m_N\), and the \(N\)-th terms of both sequences are identical: \(d_N = d_N'\). So we can safely replace \(d_N\) in equation (7) with \(d_N'\).
We can also find a recurrence between \(d_i'\) and \(d_{i-1}'\):
\[d_i' = \sum_{j=1}^{i} e^{x_j - m_i} = \left( \sum_{j=1}^{i-1} e^{x_j - m_i} \right) + e^{x_i - m_i} = \left( \sum_{j=1}^{i-1} e^{x_j - m_{i-1}} \right) e^{m_{i-1} - m_i} + e^{x_i - m_i} = d_{i-1}'\, e^{m_{i-1} - m_i} + e^{x_i - m_i} \tag{9}\]This recurrence only depends on \(m_i\) and \(m_{i-1}\), so we can compute \(m_i\) and \(d_i'\) together in the same loop.
2-pass online softmax
\[\begin{aligned} &\textbf{for } i = 1 \ldots N: \\ &\quad m_i = \max(m_{i-1},\, x_i) \\ &\quad d_i' = d_{i-1}' \cdot e^{m_{i-1} - m_i} + e^{x_i - m_i} \\[6pt] &\textbf{for } i = 1 \ldots N: \\ &\quad a_i = \dfrac{e^{x_i - m_N}}{d_N'} \end{aligned}\]It still takes two passes. And we can reduce it to a single pass to minimize global I/O. We’ll see that in the FA2 section, after we’ve covered the GPU hierarchy and tiling.
References
- From Online Softmax to FlashAttention - by Zihao Ye (notation used in this section is from here)
GPU Memory and Compute Hierarchy
We left online softmax at two passes. The piece still missing is where those chunks live and how we move them between memory levels. To understand that, and to understand why we process attention in chunks at all, we first need a mental model of how a GPU stores and computes data. That is what this section builds.
We’ll build the memory hierarchy first, then the compute side. Tiling, which combines the two, follows in the next section.
The memory hierarchy
Why a hierarchy? Memory on a GPU is layered based on functionality, bandwidth, size, and access pattern. It is very similar to a CPU’s hierarchy of HDD, RAM, cache, and registers. On a GPU, the levels are: global memory (GMEM, also called HBM, high-bandwidth memory, or off-chip memory), L2 cache, shared memory (SMEM, on-chip memory) and L1 cache, and registers. This ordering goes from largest to smallest in size, lowest to highest in bandwidth, and highest to lowest in latency.
Some rough numbers to keep in mind, for the H100 SXM specifically:
- GMEM / HBM3: ~80 GB capacity, ~3.35 TB/s bandwidth, hundreds of cycles of latency.
- L2 cache: ~50 MB, shared across the whole GPU.
- SMEM / L1: up to 228 KB per SM, configurable as a split between shared memory and L1 cache in code. Bandwidth is roughly an order of magnitude higher than HBM, with latency in the tens of cycles.
- Registers: 65536 32-bit registers per SM (often written as 64K), the fastest storage, allocated per thread.
The point of these numbers is the gap: each step down the hierarchy is dramatically faster but dramatically smaller. That tension is what every kernel optimization has to navigate.
There is a clear tradeoff in designing kernels around these hardware characteristics. This is one of the reasons I love this domain: you can clearly see what you gain and what you give up. One example is occupancy. We want to maximize the number of warps resident per SM, but to do so we need enough resources (registers, shared memory) available on that SM, and resource usage depends on how you framed the algorithm and how you use memory and registers. Balancing this is what it takes to achieve high utilization.
I highly recommend Aleksa Gordic’s writeup on NVIDIA GPU anatomy if you want more depth before proceeding.
The compute hierarchy
We’ve summarized the memory hierarchy. Let’s do a similar one for compute.
Kernels are launched as a grid, which contains multiple blocks, each of which is composed of multiple warps, and each warp is 32 threads. The number of threads per warp is fixed by hardware; warps are not directly exposed as a software unit you tune. Blocks and grids are the software-accessible, tunable units. Multiple blocks can be resident within an SM, depending on the block’s resource requirements and the SM’s available resources. All threads within a block can share that SM’s shared memory to communicate and exchange data.
That covers the structure of parallel compute. The compute units themselves, inside each SM, are: CUDA cores, Tensor cores, and Special Function Units (SFUs). Each is built for specific use cases: CUDA cores for general arithmetic, Tensor cores for matrix multiply and fused multiply-add (FMA), and SFUs for transcendental functions like exponentials.

Because these are separate hardware units, they can run in parallel. I mention this because it is one of the optimizations we’ll apply to make attention faster: use the Tensor cores for the matmuls while the CUDA cores or SFUs simultaneously handle the softmax. This is just to plant the idea; we’ll return to it in the warp specialization and ping-pong sections.
You can reference the NVIDIA H100 GPU Whitepaper for more details.
SIMT: the execution model
One more foundational idea, and arguably the foundation of GPU programming: SIMD/SIMT, Single Instruction Multiple Data / Single Instruction Multiple Threads. We issue a single instruction and apply it across many data elements at once. This is the core reason GPUs accelerate deep learning so well.
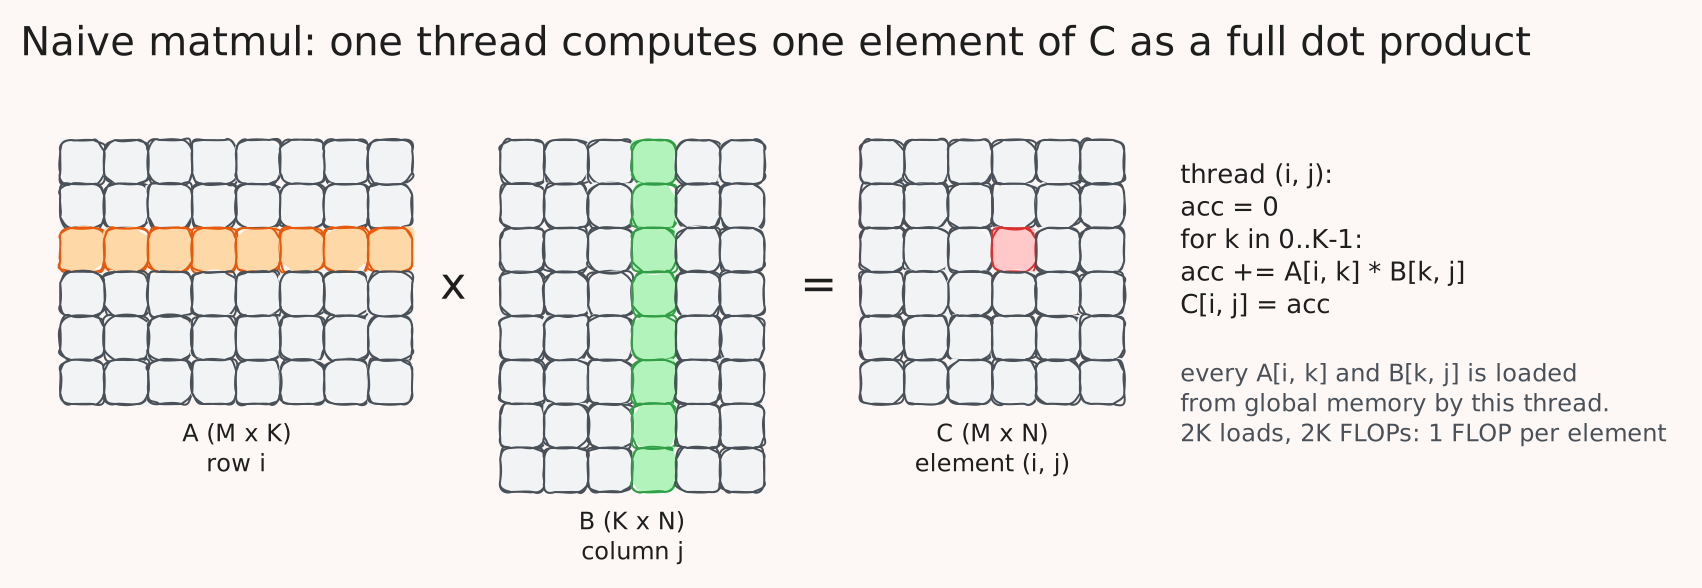
Matrix multiplication is a natural fit for this model. Each element of the output matrix is an independent dot product: element \((0,0)\) of the result is the dot product of row 0 of \(A\) with column 0 of \(B\), element \((0,1)\) is row 0 of \(A\) with column 1 of \(B\), and so on. In a basic model where one thread computes one output element, every thread runs the same instruction (a dot product) but operates on different data. That is SIMT.
This is also the bridge to the next section. The block/warp/thread structure above is how work is grouped; tiling is how we shape the data so that grouping maps cleanly onto the memory hierarchy.
Tiling
Before defining tiling, let’s see why we need it, and why it is the thing that lets us combine the memory and compute hierarchies. There are two reasons.
First, we can’t fit all the data in fast memory at once, so we break it into chunks and process them piece by piece. (This is exactly the constraint that forced online softmax into chunked processing.)
Second, we want to avoid repeated transfers from GMEM to SMEM. Moving data is where much of the time goes. HBM bandwidth, while large in absolute terms, is far lower than the rate at which the compute units can consume data, so without care the compute units sit idle waiting for data to arrive. These are memory stalls, and we want to minimize them. Since SMEM is small, we can only hold a small portion of the data at a time, which again pushes us toward breaking the data into small pieces.
Why “tiles”? Because we chunk in 2D, along both rows and columns, so each piece is a tile. The Ampere and Hopper Tensor cores consume matrix fragments directly, so tiling has become the norm, and modern libraries like Triton and CuTe expose tiles rather than scalar elements as their basic primitive.
How tiling works
Here is the standard framing, on a generic GEMM \(C = A \times B\) where \(A\) is \(M \times K\), \(B\) is \(K \times N\), and \(C\) is \(M \times N\).
Instead of one thread computing one full output element (one full dot product over the entire \(K\) dimension), we organize the work as:
- An outer loop over output tiles: the \(M \times N\) output is divided into tiles of size \(T_M \times T_N\). Each block of threads is responsible for one output tile.
- An inner loop over the \(K\) dimension: the shared dimension \(K\) is also split into chunks of size \(T_K\). For each step, the block loads one \(T_M \times T_K\) tile of \(A\) and one \(T_K \times T_N\) tile of \(B\) from GMEM into SMEM, multiplies them, and accumulates the partial result into registers.
After the inner loop finishes walking the full \(K\) dimension, the accumulator in registers holds the complete output tile, which is then written back to GMEM once.
In pseudocode:
# C = A @ B
# A: (M, K), B: (K, N), C: (M, N)
# tile sizes: T_M, T_N, T_K

for each output tile (i, j) in the (M/T_M) x (N/T_N) grid:      # outer loop, parallel across blocks
    acc = zeros(T_M, T_N)                                       # lives in registers

    for k_step in range(0, K, T_K):                             # inner loop over K
        A_tile = load A[i*T_M : (i+1)*T_M, k_step : k_step+T_K]  # GMEM -> SMEM
        B_tile = load B[k_step : k_step+T_K, j*T_N : (j+1)*T_N]  # GMEM -> SMEM
        acc += A_tile @ B_tile                                  # compute on SMEM data

    C[i*T_M : (i+1)*T_M, j*T_N : (j+1)*T_N] = acc               # SMEM/registers -> GMEM
The inner \(K\)-loop is pure accumulation: each \(K\)-step loads a fresh pair of tiles and adds its partial product into acc. The loop walks the shared dimension in \(K/T_K\) steps, and only after the last step does acc hold a complete output tile.
Compare this with the naive version, where each output element is computed independently and every access goes to GMEM:
# naive: one thread, one output element
for i in range(M):
    for j in range(N):
        acc = 0
        for k in range(K):
            acc += A[i, k] * B[k, j]    # every read hits GMEM
        C[i, j] = acc
To tie this back to the compute hierarchy from the previous section, here is how the tiling concepts map onto the GPU’s parallel execution units:
| Tiling concept | Hardware unit | Role |
|---|---|---|
| The full output grid of tiles | grid | The whole launch. One grid covers the entire \(M \times N\) output. |
| One output tile \((i, j)\) | thread block | One block owns one output tile and runs the inner \(K\)-loop for it. Blocks are independent, so all output tiles can be computed in parallel. |
| A sub-tile within the block’s tile | warp (32 threads) | The block’s tile is further divided among its warps, with each warp cooperatively computing a portion. |
| One output element (or small group) | thread | The finest unit of work, executing the same instruction as its warp-mates on different data (SIMT). |
A_tile, B_tile | shared memory (SMEM) | Loaded once from GMEM per \(K\)-step, then read many times by all threads in the block. This shared reuse is why the load is amortized. |
acc (the accumulator) | registers | Per-thread, holds the partial result across the entire inner loop. Written to GMEM only once, at the end. |
The key thing this mapping makes clear: the grid/block split is what gives us parallelism across output tiles, while the SMEM/register split is what gives us data reuse within a tile. Tiling works because it exploits both at once. (The warp-level detail, how a warp’s threads cooperate with the Tensor cores on a fragment, is deferred to the WGMMA section.)
We’ve described what the loops do and how the work maps to hardware. The next subsection makes the payoff concrete: it counts the memory traffic and shows exactly why this structure is faster.
Why tiling reduces memory traffic
The intuition that tiling helps becomes concrete once we count. We’ll count GMEM traffic in elements rather than bytes; the bytes-per-element factor is the same for both versions, so it cancels in the final ratio. For simplicity, assume square tiles of size \(T \times T\) (so \(T_M = T_N = T_K = T\)).
Naive version. Each output element of \(C\) is one dot product over the full \(K\) dimension. Computing it reads \(K\) elements of \(A\) and \(K\) elements of \(B\) from GMEM, so \(2K\) reads per output element. There are \(M \cdot N\) output elements, so total GMEM traffic is:
\[Q_{\text{naive}} = 2 \cdot M \cdot N \cdot K \quad \text{elements}\]The useful compute is one multiply and one add per term, over \(K\) terms, for each of the \(M \cdot N\) outputs:
\[W = 2 \cdot M \cdot N \cdot K \quad \text{FLOPs}\]The arithmetic intensity is the ratio of compute to memory traffic:
\[I_{\text{naive}} = \frac{W}{Q_{\text{naive}}} = \frac{2 \cdot M \cdot N \cdot K}{2 \cdot M \cdot N \cdot K} = 1 \quad \text{FLOP per element}\]One FLOP per element moved. The kernel is entirely memory-bound: the compute units do a single operation for every value dragged across the slow GMEM boundary.
Tiled version. Now the output is divided into \((M/T) \times (N/T)\) tiles. For each output tile, the inner loop walks the \(K\) dimension in \(K/T\) steps. At each step it loads one \(T \times T\) tile of \(A\) and one \(T \times T\) tile of \(B\), which is \(2T^2\) elements. So the GMEM traffic for a single output tile is:
\[\frac{K}{T} \cdot 2T^2 = 2 \cdot T \cdot K \quad \text{elements}\]There are \(\dfrac{M \cdot N}{T^2}\) output tiles in total, so:
\[Q_{\text{tiled}} = \frac{M \cdot N}{T^2} \cdot 2 \cdot T \cdot K = \frac{2 \cdot M \cdot N \cdot K}{T} \quad \text{elements}\]The compute \(W\) is unchanged, \(2 \cdot M \cdot N \cdot K\) FLOPs, since tiling reorganizes the work but does not remove any of it. The arithmetic intensity becomes:
\[I_{\text{tiled}} = \frac{W}{Q_{\text{tiled}}} = \frac{2 \cdot M \cdot N \cdot K}{\,2 \cdot M \cdot N \cdot K \,/\, T\,} = T \quad \text{FLOPs per element}\]The ratio. Comparing the two:
\[\frac{I_{\text{tiled}}}{I_{\text{naive}}} = \frac{T}{1} = T\]Tiling improves arithmetic intensity by a factor of \(T\), the tile size. Equivalently, it cuts GMEM traffic by a factor of \(T\) for the same amount of compute.
Where the factor of \(T\) comes from. It is worth seeing why the ratio is exactly \(T\), because the reuse happens at a finer level than “load tile A, load tile B.” The line acc += A_tile @ B_tile looks like a single operation, but multiplying two \(T \times T\) tiles is itself a \(T \times T \times T\) triple loop: every row of A_tile must be dotted with every column of B_tile. So a single row of A_tile, once it sits in SMEM, is read \(T\) times, once for each output column, rather than being fetched from GMEM \(T\) separate times. Likewise each column of B_tile is reused across all \(T\) rows. In numbers: the tile-tile multiply does \(2T^3\) FLOPs of compute on only \(2T^2\) loaded elements, so each loaded element is touched \(T\) times. That is the factor of \(T\). Note that this reuse lives inside the tile-tile multiply, not across \(K\)-steps: each \(K\)-step still loads a fresh pair of tiles, but each loaded tile, once in SMEM, earns \(T\) uses before being discarded.
What the factor of \(T\) buys you. To see why this matters, compare arithmetic intensity against real hardware. For H100 SXM in BF16, the Tensor cores deliver roughly 990 TFLOP/s of compute, while HBM3 delivers roughly 3.35 TB/s of bandwidth. To stay consistent with our element-based traffic count, we convert that bandwidth into elements per second: at 2 bytes per BF16 element, 3.35 TB/s is about \(1.675 \times 10^{12}\) elements/s. Dividing compute by bandwidth gives the hardware’s break-even arithmetic intensity:
\[I_{\text{ridge}} = \frac{990 \times 10^{12} \text{ FLOP/s}}{1.675 \times 10^{12} \text{ elem/s}} \approx 590 \text{ FLOPs per element}\]This is the roofline model: a kernel’s attainable performance is capped by whichever constraint binds first, memory bandwidth or peak compute. The crossover is the ridge point: any kernel below it is memory-bound, any kernel above it is compute-bound. A naive GEMM sits at \(I = 1\), nearly 600× below the threshold. The Tensor cores can compute almost 600 times faster than HBM can feed them, so they spend the overwhelming majority of their time idle, waiting on data. Tiling raises \(I\) from 1 toward \(T\), moving the kernel up the roofline, toward the regime where compute, not memory, is the limit.
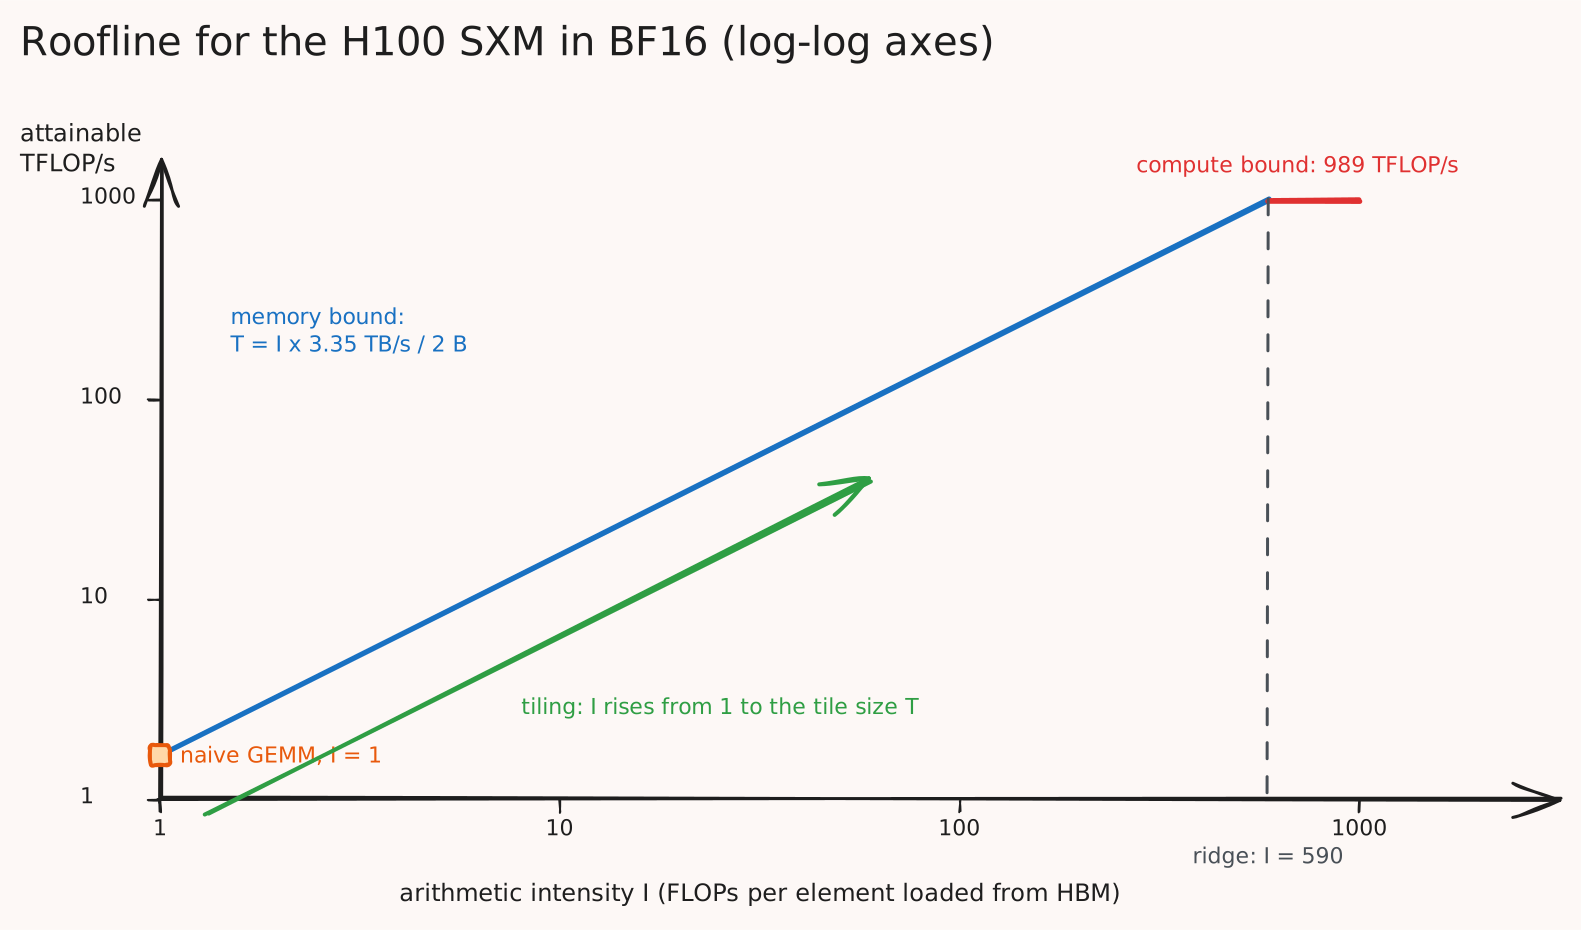
This is the whole game. Tiling does not reduce compute; it reduces how many times each value crosses the slow GMEM boundary, moving the kernel from memory-bound (\(I = 1\)) toward compute-bound (\(I = T\)), which is the regime where the Tensor cores can actually be kept busy.
We’ll cover how this same tiling idea applies to attention, where the second matmul (\(P \times V\)) depends on the softmax output of the first, in the FA2 section. The attention case has an extra wrinkle that plain GEMM does not, and online softmax is what resolves it.
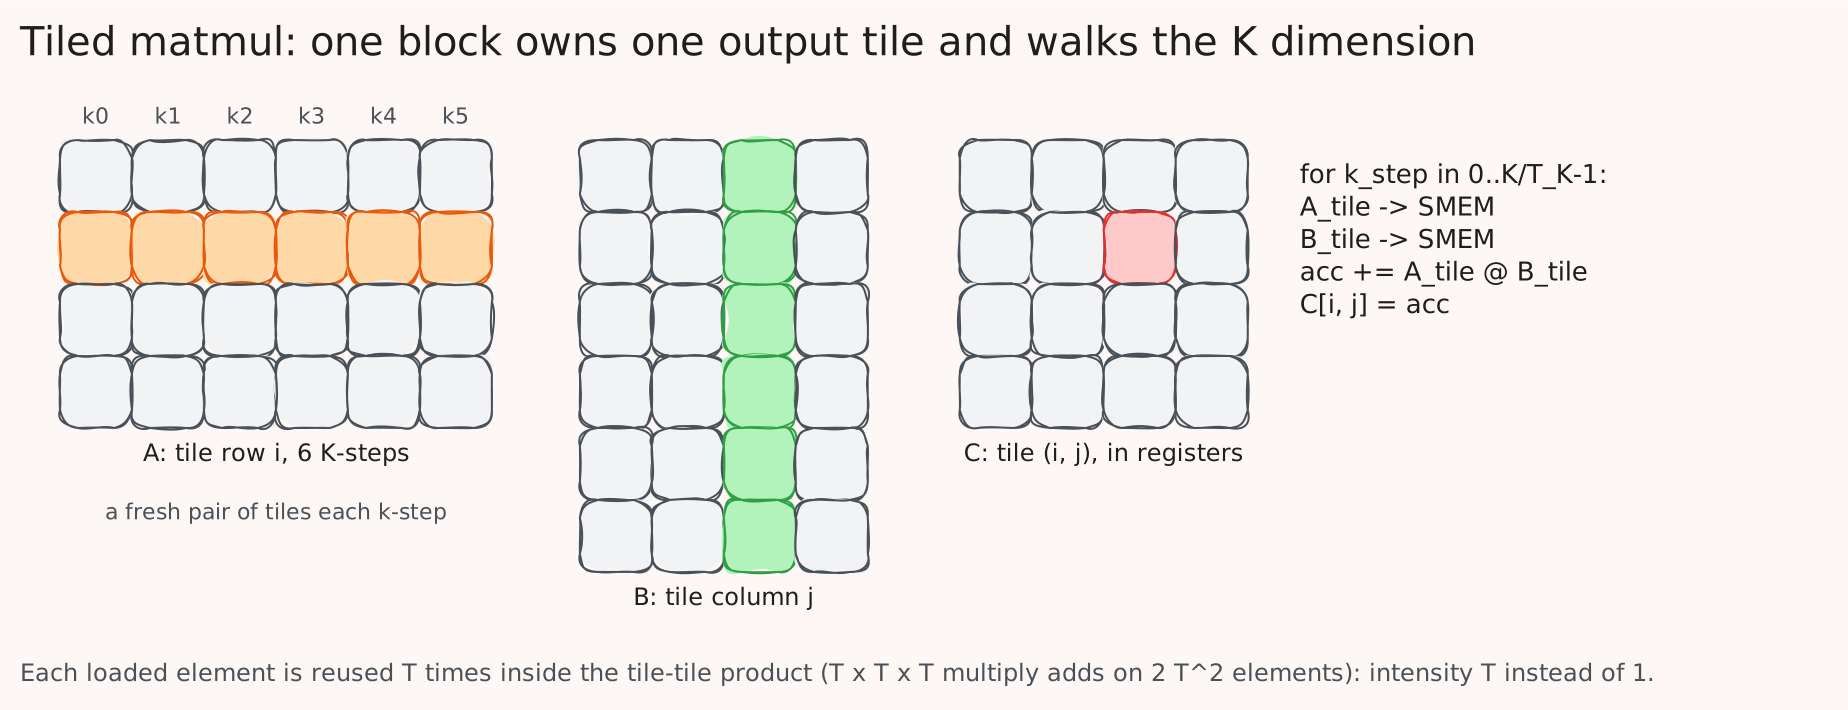
For a deeper, code-level walkthrough of GEMM tiling, see Simon’s GEMM worklog.
References
- How to Optimize a CUDA Matmul Kernel for cuBLAS-like Performance: a Worklog - Simon Boehm
- Inside NVIDIA GPUs: Anatomy of high performance matmul kernels - Aleksa Gordić
- NVIDIA H100 GPU Whitepaper
FlashAttention-2 (FA2)
Now that we have all the basic building blocks we need to construct FlashAttention, let’s do it.
First and foremost: FA1 and FA2 are very similar. They differ only in loop ordering and in what is kept in shared memory. We’ll look at FA2 directly. The algorithm at its core is also the same for FA3, so getting it clear here lets us relate to and build on it for the rest of the blog.
Before we get into the GPU-specific details, let’s do the math-heavy part first. The UWashington paper by Zihao Ye does a very good job of this, so we’ll use it as our reference here.
A quick note on notation before the derivation begins. We adopt the paper’s bracket-index style for this section, because shapes will matter at every step and bracket notation makes them self-documenting:
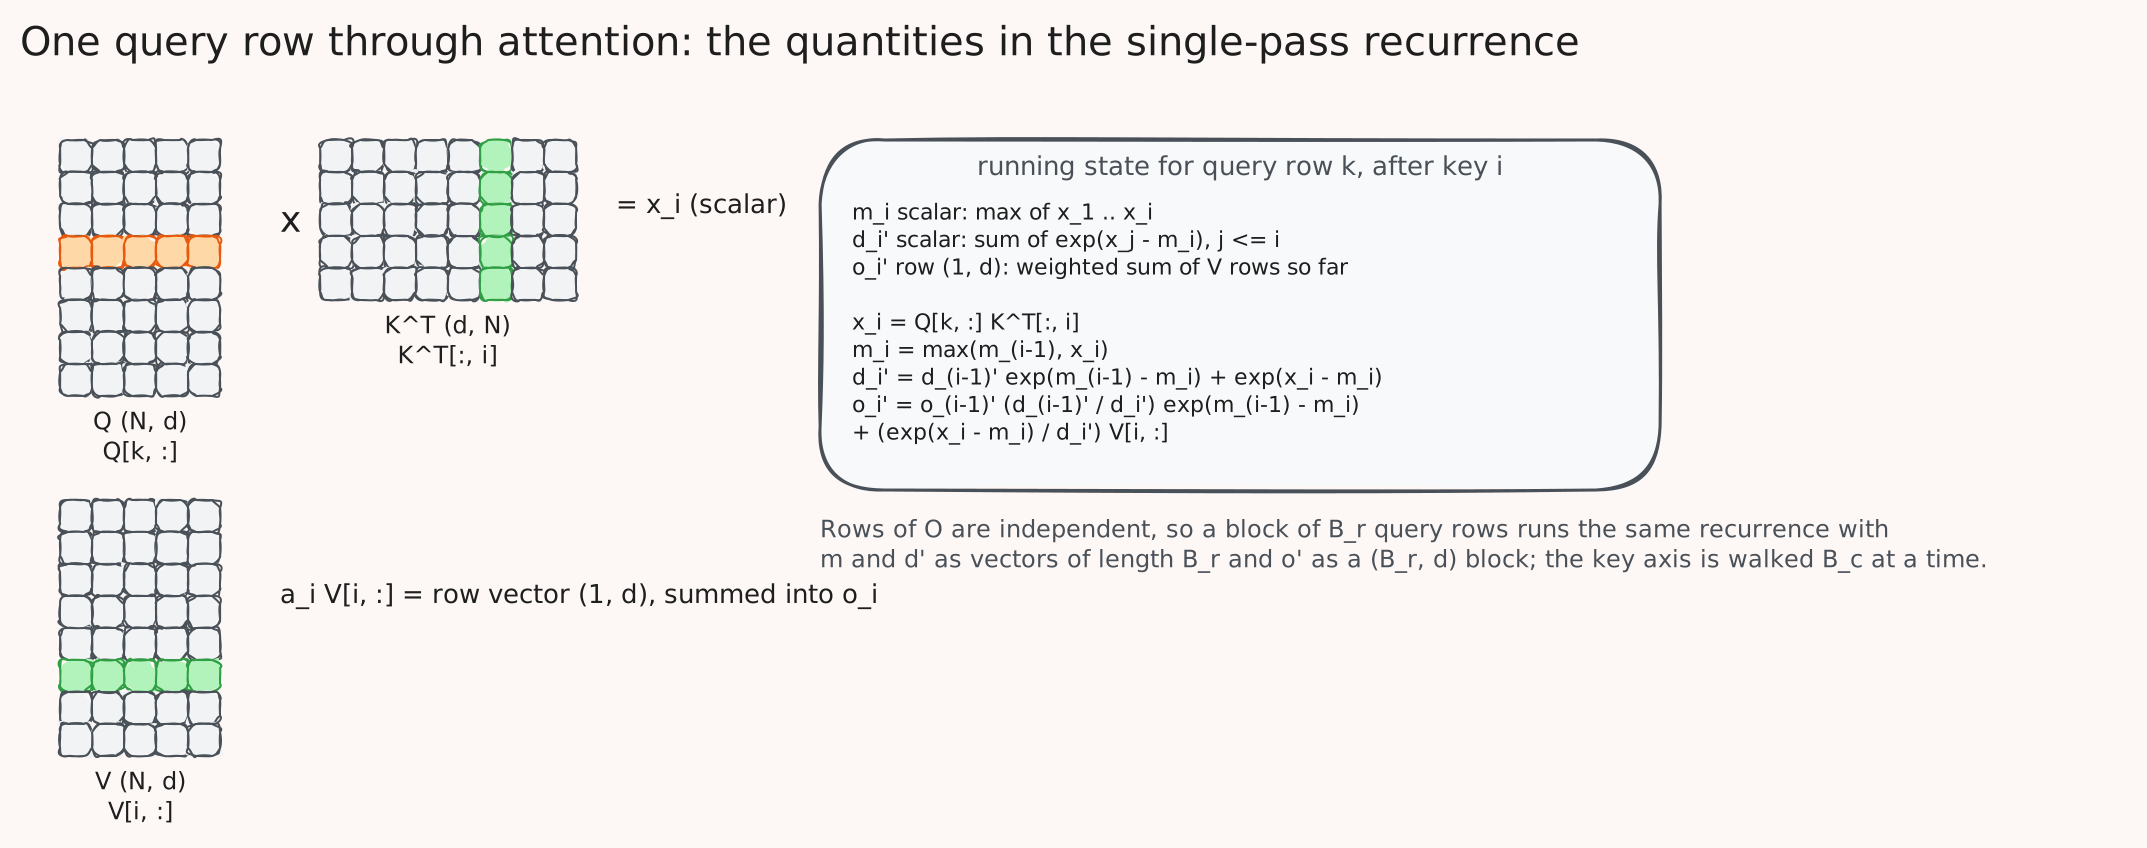
- \(Q[k, :]\): the \(k\)-th row of the \(Q\) matrix, shape \((1, d)\).
- \(K^\top[:, i]\): the \(i\)-th column of \(K^\top\), shape \((d, 1)\).
- \(V[i, :]\): the \(i\)-th row of the \(V\) matrix, shape \((1, d)\).
- \(O[k, :]\): the \(k\)-th row of the output matrix \(O\), shape \((1, d)\).
The running scalars and row vectors carry over from the online-softmax section: \(m_i\) is the running max, \(d_i'\) is the running (surrogate) softmax denominator (both scalars), and we now add \(o_i'\), the running (surrogate) output accumulator (a row vector of shape \((1, d)\)). The computation of every output row is independent, so we explain it for a single row.
Also, as in the online-softmax section, we drop the \(1/\sqrt{d}\) softmax scale and the causal mask here for simplicity. Both are present in real code: the scale keeps the dot products from saturating the softmax as \(d\) grows, and the causal mask ensures each query attends only to keys at or before its position. We omit them only to keep the recurrence readable.
From multi-pass to single-pass attention
In the online-softmax section we asked whether softmax could be done in one pass and the answer was no. But in self-attention our final target is not the attention-score matrix \(A\). It is the output matrix \(O = A V\). So the better question is: can we find a one-pass recurrence for \(O\) instead?
With the notation in hand from the section intro, we add three more symbols specific to this derivation:
- \(x_i\): a scalar, the \(i\)-th attention score. Comes from a row times a column: \(x_i = Q[k, :]\, K^\top[:, i]\).
- \(a_i\): a scalar, the \(i\)-th softmax weight.
- \(o_i\): a row vector of shape \((1, d)\), the partial aggregation \(\sum_{j=1}^{i} a_j\, V[j, :]\). This is the running output state.
We can now write the per-row attention computation as a recurrence. We reuse the 2-pass online softmax from before, and add a second loop that accumulates the output row.
Multi-pass self-attention.
\[\begin{aligned} &\textbf{for } i = 1 \ldots N: \\ &\quad x_i \leftarrow Q[k, :]\, K^\top[:, i] \\ &\quad m_i \leftarrow \max(m_{i-1},\, x_i) \\ &\quad d_i' \leftarrow d_{i-1}'\, e^{m_{i-1} - m_i} + e^{x_i - m_i} \\[6pt] &\textbf{for } i = 1 \ldots N: \\ &\quad a_i \leftarrow \dfrac{e^{x_i - m_N}}{d_N'} &(10)\\ &\quad o_i \leftarrow o_{i-1} + a_i\, V[i, :] &(11)\\[6pt] &O[k, :] \leftarrow o_N \end{aligned}\]A few things to read off this:
- In equation (10), \(a_i\) is scalar: \(x_i, m_N, d_N'\) are all scalars.
- In equation (11), \(a_i\, V[i, :]\) is a scalar times a row vector, producing a row vector of shape \((1, d)\). Adding it to \(o_{i-1}\) (also \((1, d)\)) gives \(o_i\) of shape \((1, d)\). So \(o_i\) accumulates a sum of \(d\)-dimensional row vectors, one per loop iteration.
- After the loop, \(o_N = \sum_{j=1}^{N} a_j\, V[j, :]\), which is the \(k\)-th row of \(O\).
This is multi-pass: the second loop cannot start until the first finishes, because \(a_i\) in equation (10) depends on \(m_N\) and \(d_N'\), which are only known after the first loop completes.
Fusing into a single pass
To fuse the two loops we have to remove the dependency on \(m_N\) and \(d_N'\). Start by substituting the definition of \(a_i\) from equation (10) into equation (11):
\[o_i := \sum_{j=1}^{i} \frac{e^{x_j - m_N}}{d_N'}\, V[j, :] \quad (12)\]Same dependency problem: \(m_N\) and \(d_N'\) aren’t available inside the loop. We play the same surrogate trick we used for \(d_i'\) in the online-softmax section: define a surrogate sequence \(o_i'\) that uses the running values \(m_i\) and \(d_i'\) instead of the final \(m_N\) and \(d_N'\):
\[o_i' := \sum_{j=1}^{i} \frac{e^{x_j - m_i}}{d_i'}\, V[j, :]\]The \(N\)-th terms of the two sequences agree. Setting \(i = N\) in the surrogate definition, the running \(m_i\) and \(d_i'\) become the final \(m_N\) and \(d_N'\):
\[o_N' = \sum_{j=1}^{N} \frac{e^{x_j - m_N}}{d_N'}\, V[j, :] = o_N\]The right-hand side is exactly the definition of \(o_N\) from equation (12). So computing the surrogate \(o_N'\) gives us the true output. The reason this works is the same as for \(d_i'\): only the final term of the sequence is needed, and at the final term the running statistics have caught up to the global ones. Revisit the online-softmax section for the fuller argument.
Next we find a recurrence between \(o_i'\) and \(o_{i-1}'\). The goal is to write \(o_i'\) in terms of \(o_{i-1}'\), a constant, and the data of step \(i\). We walk it step by step.
Start from the definition of \(o_i'\) and split off the last term (\(j = i\)):
\[o_i' = \sum_{j=1}^{i} \frac{e^{x_j - m_i}}{d_i'}\, V[j, :] = \left( \sum_{j=1}^{i-1} \frac{e^{x_j - m_i}}{d_i'}\, V[j, :] \right) + \frac{e^{x_i - m_i}}{d_i'}\, V[i, :]\]Now we need to massage the first sum so it matches the definition of \(o_{i-1}'\). By definition, \(o_{i-1}' = \sum_{j=1}^{i-1} \frac{e^{x_j - m_{i-1}}}{d_{i-1}'} V[j, :]\). The first sum above has \(m_i\) and \(d_i'\) where we’d like \(m_{i-1}\) and \(d_{i-1}'\). We change them one at a time.
First, rewrite the exponent. Using \(e^{x_j - m_i} = e^{x_j - m_{i-1} + m_{i-1} - m_i} = e^{x_j - m_{i-1}}\, e^{m_{i-1} - m_i}\):
\[\sum_{j=1}^{i-1} \frac{e^{x_j - m_i}}{d_i'}\, V[j, :] = \sum_{j=1}^{i-1} \frac{e^{x_j - m_{i-1}}\, e^{m_{i-1} - m_i}}{d_i'}\, V[j, :]\]The factor \(e^{m_{i-1} - m_i}\) doesn’t depend on \(j\), so it can come out of the sum:
\[= e^{m_{i-1} - m_i} \sum_{j=1}^{i-1} \frac{e^{x_j - m_{i-1}}}{d_i'}\, V[j, :]\]Now we still have \(d_i'\) where we’d like \(d_{i-1}'\). Multiply and divide by \(d_{i-1}'\):
\[= e^{m_{i-1} - m_i}\, \frac{d_{i-1}'}{d_i'} \sum_{j=1}^{i-1} \frac{e^{x_j - m_{i-1}}}{d_{i-1}'}\, V[j, :]\]The sum is now exactly \(o_{i-1}'\). Substituting:
\[\sum_{j=1}^{i-1} \frac{e^{x_j - m_i}}{d_i'}\, V[j, :] = o_{i-1}'\, \frac{d_{i-1}'}{d_i'}\, e^{m_{i-1} - m_i}\]Plug back into the split form of \(o_i'\):
\[o_i' = o_{i-1}'\, \frac{d_{i-1}'}{d_i'}\, e^{m_{i-1} - m_i} + \frac{e^{x_i - m_i}}{d_i'}\, V[i, :] \quad (13)\]The recurrence (13) depends only on \(d_i', d_{i-1}', m_i, m_{i-1}, x_i,\) and \(V[i, :]\). Every one of these is available within a single loop iteration, so we can fuse the entire attention computation into one pass:
FlashAttention (single-pass).
\[\begin{aligned} &\textbf{for } i = 1 \ldots N: \\ &\quad x_i \leftarrow Q[k, :]\, K^\top[:, i] \\ &\quad m_i \leftarrow \max(m_{i-1},\, x_i) \\ &\quad d_i' \leftarrow d_{i-1}'\, e^{m_{i-1} - m_i} + e^{x_i - m_i} \\ &\quad o_i' \leftarrow o_{i-1}'\, \dfrac{d_{i-1}'}{d_i'}\, e^{m_{i-1} - m_i} + \dfrac{e^{x_i - m_i}}{d_i'}\, V[i, :] \\[6pt] &O[k, :] \leftarrow o_N' \end{aligned}\]A note on the shapes inside the loop: every operation on the right side of the \(o_i'\) update is a scalar coefficient multiplying either \(o_{i-1}'\) (a \((1, d)\) row) or \(V[i, :]\) (a \((1, d)\) row). The result is a \((1, d)\) row, matching \(o_i'\)’s shape. The expensive part of one iteration is the row addition; the rest is scalar arithmetic.
The states \(x_i, m_i, d_i',\) and \(o_i'\) all have small footprints that fit comfortably in GPU shared memory: three scalars and one \((1, d)\) row per query. This is the property that makes FlashAttention work. We never materialize the full \(N \times N\) score matrix, only a handful of running states per row.
Tiling the algorithm
The single-pass algorithm processes the entire sequence as a loop over individual key/value indices. Tiling changes how many rows we process per loop step, in two independent ways. We do them one at a time. Step 1 follows the paper exactly: tile the key/value sequence dimension. Step 2 extends the same idea to query rows, which lifts us into the form the real kernel uses (Algorithm 1).
Step 1: tiling the key/value rows.
The paper does this step first because all operations in the single-pass algorithm are associative: nothing forces us to process one \(K^\top\) column and one \(V\) row at a time. We can process a block of them in one loop step, as long as the recurrence’s max-tracking and rescaling still work.
We do not touch the query row. \(Q[k, :]\) stays whole. What we tile is the key/value sequence dimension: instead of walking it one row at a time, we walk it \(b\) rows at a time, where \(b\) is the tile size.
New notations for this step (matching the paper):
- \(b\): the block size of the tile.
- \(\#\text{tiles} = N / b\): number of tiles in one row of the score matrix.
- \(x_i\): now a row vector of shape \((1, b)\), holding the dot products of \(Q[k, :]\) against the \(i\)-th tile of \(K^\top\). So \(x_i = Q[k, :]\, K^\top[:, (i-1)b : ib]\), covering columns \((i-1)b + 1\) through \(ib\).
- \(x_i[j]\): the \(j\)-th entry of \(x_i\) (scalar). It’s the score of \(Q[k, :]\) against the \(j\)-th key row inside tile \(i\).
- \(m_i^{(\text{local})}\): scalar, the local maximum within \(x_i\).
- \(m_i, d_i', o_i'\): same running states as before (two scalars and one row vector of shape \((1, d)\)). They now update per tile instead of per row.
With those, the tiled algorithm is:
\[\begin{aligned} &\textbf{for } i = 1 \ldots \#\text{tiles}: \\ &\quad x_i \leftarrow Q[k, :]\, K^\top[:, (i-1)b : ib] \\ &\quad m_i^{(\text{local})} \leftarrow \max_{j = 1 \ldots b}\, x_i[j] \\ &\quad m_i \leftarrow \max\!\left(m_{i-1},\, m_i^{(\text{local})}\right) \\ &\quad d_i' \leftarrow d_{i-1}'\, e^{m_{i-1} - m_i} + \sum_{j=1}^{b} e^{x_i[j] - m_i} \\ &\quad o_i' \leftarrow o_{i-1}'\, \dfrac{d_{i-1}'}{d_i'}\, e^{m_{i-1} - m_i} + \sum_{j=1}^{b} \dfrac{e^{x_i[j] - m_i}}{d_i'}\, V[j + (i-1)b, :] \\[6pt] &O[k, :] \leftarrow o_{N/b}' \end{aligned}\]Reading it: \(m_i^{(\text{local})}\) is the max within the current tile only, and the regular \(m_i\) folds that local max into the running global max. The \(d_i'\) update is the same recurrence as before, except the new contribution is a sum over the \(b\) entries of \(x_i\) instead of a single \(e^{x_i - m_i}\). The \(o_i'\) update similarly: the per-step contribution is now a sum of \(b\) scaled value rows. Nothing in the algorithm structure changed; we just process \(b\) entries per loop step instead of one.
This is the form the paper stops at. The states \(x_i, m_i, d_i', o_i'\) all still have small footprints that fit comfortably in GPU shared memory (the largest is \(o_i'\), one row vector of \(d\) elements). One loop step now consumes a whole \((b, d)\) tile of \(K^\top\) and \(V\), which is what lets each tile be loaded into SMEM once and fully consumed there.
Step 2: tiling the query rows.
The paper’s algorithm stops at K/V tiling, but the real kernel (Algorithm 1 below) also tiles query rows. So we take one more step.
So far we have processed one query row \(Q[k, :]\). But every output row is computed independently: row \(k\) of \(O\) never depends on row \(k'\). That independence means we don’t need a new recurrence to handle many query rows. We just run the Step 1 recurrence for a block of query rows at once, and every per-row quantity gains a row dimension. The paper’s \(b\) becomes \(B_c\) (the K/V tile size, “c” for the column dimension of the score matrix), and we introduce \(B_r\) (the Q tile size, “r” for the row dimension).
Concretely, lift each shape:
- The query block becomes \(Q_{[\,\cdot\,]}\) of shape \((B_r, d)\) instead of one row.
- The score \(x_i\) becomes a matrix of shape \((B_r, B_c)\), where row \(r\) contains the scores of query row \(r\) against all \(B_c\) key rows of tile \(i\).
- The running statistics \(m_i\) and \(d_i'\) become vectors of shape \((B_r,)\), one value per query row.
- The running output \(o_i'\) becomes a block of shape \((B_r, d)\).
- \(V_{[(i-1)B_c : iB_c]}\) is the \(i\)-th K/V tile of shape \((B_c, d)\), same as Step 1.
The scalar reductions inside the loop become per-row reductions: the max over a tile becomes a rowmax (reduce the \(B_c\) axis, one max per query row), and the sum becomes a rowsum. The recurrence is otherwise identical:
A note on the shapes inside the loop: \(m_i\) is a \((B_r,)\) vector, so in \(x_i - m_i\) it broadcasts across the \(B_c\) columns of the \((B_r, B_c)\) score matrix. In the \(o_i'\) update, the per-row scalars \(\frac{d_{i-1}'}{d_i'} e^{m_{i-1} - m_i}\) and \(\frac{1}{d_i'}\) multiply each query row of the output block. \(\text{diag}(\cdot)\) is the cleanest notation for this: \(\text{diag}(v)\) turns a length-\(B_r\) vector \(v\) into a \(B_r \times B_r\) diagonal matrix, so that \(\text{diag}(v)\, M\) scales row \(r\) of matrix \(M\) by entry \(v[r]\). There is no new algebra here, just the Step 1 recurrence with a row index attached.
With both tilings in place, one loop step now processes a full \((B_r, B_c)\) score tile: a block of query rows against a block of key/value rows, with all running state held as small \((B_r,)\) vectors and one \((B_r, d)\) output block. This is the form that maps directly onto the GPU, which is the next subsection.
Mapping to hardware
The general mechanics of tiling, the grid/block/warp split, and SMEM-versus-register reuse were covered in the tiling section. Here we cover what is specific to attention, and one important point up front: the hardware mapping does not line up one-to-one with the clean mental model from the tiled algorithm above. The algorithm is a sequential recurrence over rows and tiles; the hardware is a mesh of warps and Tensor cores that only goes fast when work is shaped to fit them. Bridging that gap is exactly what the kernel sections (K1 to K8) are about. Here we set up the correct picture so the algorithm walkthrough that follows is straightforward.
The outer loop: blocks over query tiles.
This part does match the mental model. The work is parallelized over query blocks: each thread block takes one \(B_r \times d\) block of query rows and computes the corresponding \(B_r \times d\) block of output rows. Output rows are independent (the property we used to tile Q), so blocks are fully independent and the GPU schedules them across SMs with no inter-block communication. This is the outer loop, line 3 of Algorithm 1.
The inner loop: where the mental model and the hardware diverge.
In the tiled algorithm, the inner loop reads as a simple sequential sweep: for each key/value tile, compute the score tile, update \(m\), \(d'\), \(o'\), move on. It is tempting to map this as “one thread (or one warp) owns one query row and runs the recurrence for it.” That model is intuitive but wrong, and it is worth seeing why, because the real mapping is what every later optimization builds on.
The inner loop’s heavy work is two matmuls:
- \(S = Q_i K_j^\top\), producing a \(B_r \times B_c\) score tile (the first matmul),
- \(\tilde{P} V_j\), producing the \(B_r \times d\) output contribution (the second matmul).
A matmul tile on a modern GPU is not computed by independent per-row threads. It is computed cooperatively by warps through the Tensor cores. A Tensor core consumes a fragment: a small matrix shard whose elements are spread across all 32 lanes of a warp. A single thread does not hold a full row of the result, it holds a few scattered elements of the fragment. So the \(B_r\) query rows of the block are partitioned across the block’s warps as a byproduct of the matmul fragment layout, not by an explicit “row \(r\) → thread \(r\)” assignment.
This has a direct consequence for the softmax. The rowmax and rowsum in the recurrence are reductions along a row, over the \(B_c\) score values for a given query row. But after the first matmul, those \(B_c\) values for one row are spread across multiple lanes of a warp. Computing the max or sum for that row therefore requires warp-level coordination, lanes exchanging partial results through warp-shuffle instructions, not a single thread looping over the row. So the inner loop is genuinely cooperative: warps work together on the matmul tiles, and again on the cross-lane reductions for the softmax statistics, and again on the rescaling of the running output.
So the corrected picture of one inner-loop step is: the block’s warps cooperatively compute the \(S\) tile on the Tensor cores, cooperatively reduce it row-wise (warp shuffles) to get \(m^{(\text{local})}\) and the denominator update, cooperatively rescale the running output, and cooperatively compute the \(\tilde{P} V\) matmul on the Tensor cores. The sequential recurrence is still exactly what executes, it is just executed by a team of warps per step rather than by one thread per row.
The precise fragment layout, how many warps cooperate, and how the two matmuls are scheduled relative to the softmax, depend on the GPU generation. On Hopper this is the warpgroup-level WGMMA instruction, and getting it right (overlapping the matmuls with the softmax, keeping the Tensor cores fed) is the substance of the later kernel sections. We will cover WGMMA and that scheduling in the K4 section; here it is enough to hold the model that the inner loop is warp-cooperative, not per-thread.
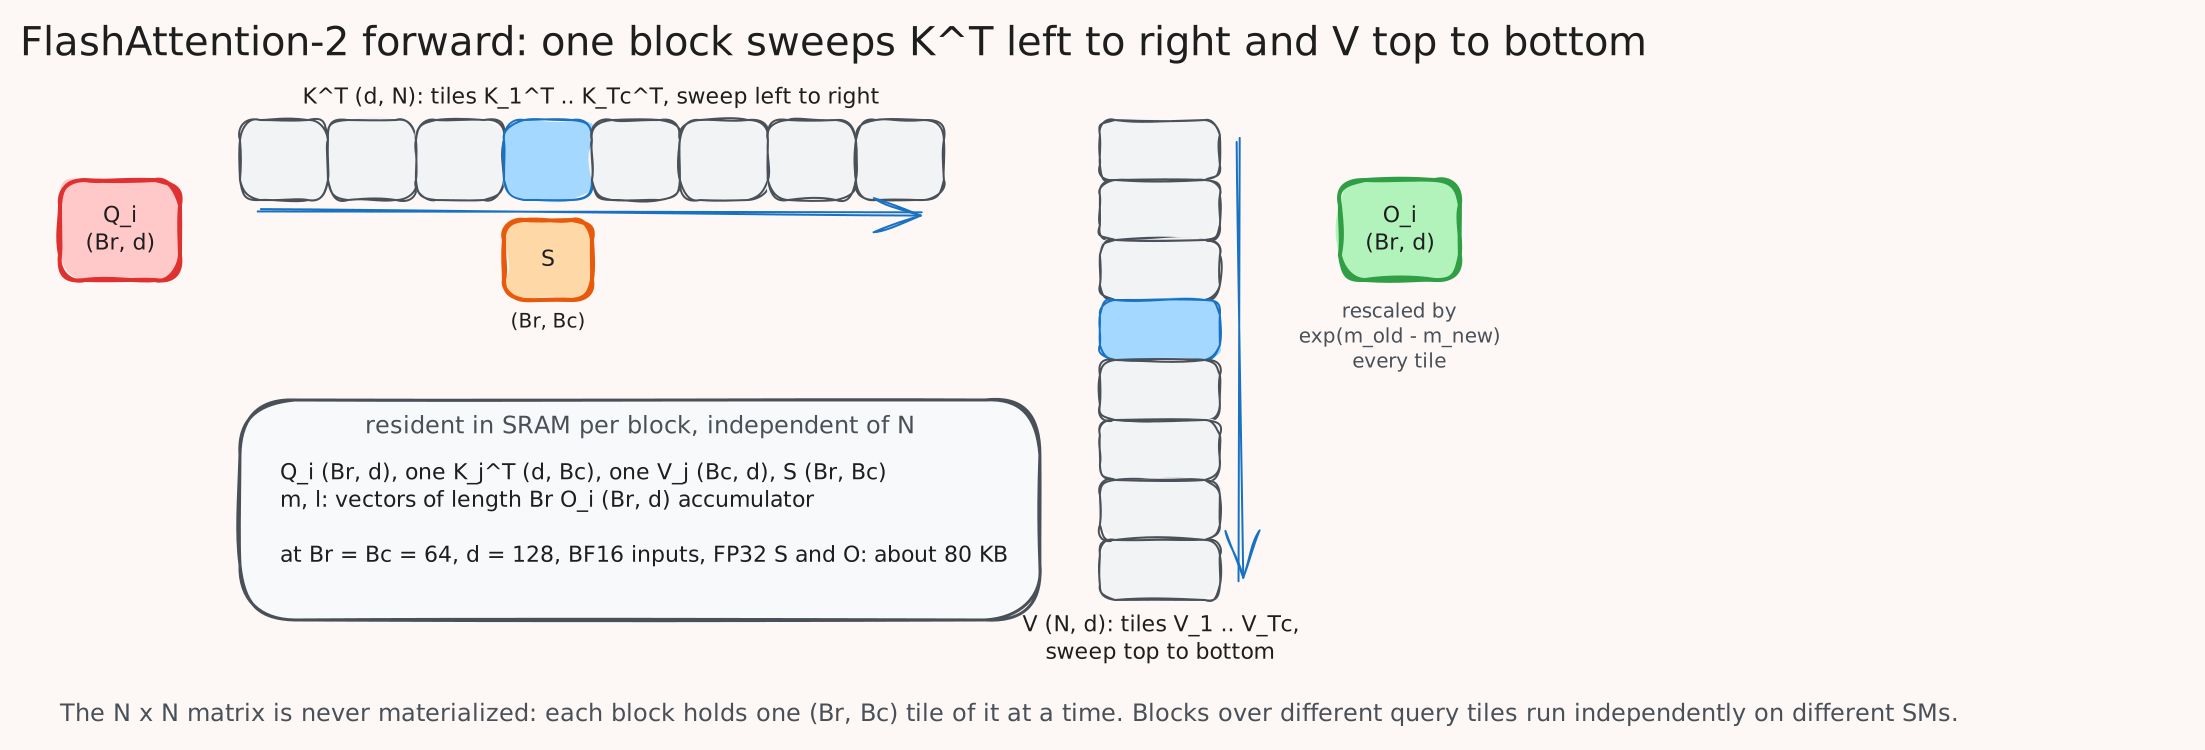
The sweep direction itself is simple: a block walks the \(K^\top\) tiles left to right and the \(V\) tiles top to bottom, updating the running state \(m\), \(d'\), \(O\) after each tile.
Why the footprint is what makes this work.
The SRAM footprint of a block depends only on the block sizes (\(B_r\), \(B_c\)) and the head dimension \(d\), never on the sequence length \(L\). At any moment a block holds only its current Q tile, one K tile, one V tile, and the small \((B_r,)\) running-state vectors, all sized by the block parameters and \(d\). The \(N \times N\) score matrix is never materialized. Since shared memory is small (228 KB/SM on H100) and \(L\) can be very large (16k or more), this \(L\)-independence is exactly what lets FlashAttention scale to long context without running out of memory.
This connects back to the occupancy tradeoff from the memory and compute hierarchy section: because the footprint is fixed by the block parameters and \(d\), the block size becomes a tuning knob. Larger blocks mean more reuse per tile but more SRAM and registers per block, which lowers how many blocks can be resident per SM. That balance is exactly the kind of tradeoff we’ll revisit when we profile real kernels.
With this mapping in mind, blocks over query tiles, warp-cooperative inner loop over key/value tiles, two Tensor-core matmuls bridged by a warp-reduced softmax, the full algorithm reads directly off the hardware.
The full algorithm: FlashAttention-2 forward pass
We have now built the algorithm twice: as a per-row recurrence, and as the \(B_r \times B_c\) tiled form that maps onto the hardware. Algorithm 1 below is that same algorithm exactly as the FA2 paper states it. It is kept in the paper’s own notation so it can serve as a faithful reference; the mapping back to the blog’s notation follows.
Algorithm 1: FlashAttention-2 forward pass
Require: Matrices \(Q, K, V \in \mathbb{R}^{N \times d}\) in HBM, block sizes \(B_c\), \(B_r\).
- Divide \(Q\) into \(T_r = \lceil N / B_r \rceil\) blocks \(Q_1, \ldots, Q_{T_r}\) of size \(B_r \times d\) each, and divide \(K, V\) into \(T_c = \lceil N / B_c \rceil\) blocks \(K_1, \ldots, K_{T_c}\) and \(V_1, \ldots, V_{T_c}\), of size \(B_c \times d\) each.
- Divide the output \(O \in \mathbb{R}^{N \times d}\) into \(T_r\) blocks \(O_1, \ldots, O_{T_r}\) of size \(B_r \times d\) each, and divide the logsumexp \(L\) into \(T_r\) blocks \(L_1, \ldots, L_{T_r}\) of size \(B_r\) each.
- for \(1 \le i \le T_r\) do
- Load \(Q_i\) from HBM to on-chip SRAM.
- On chip, initialize \(O_i^{(0)} = (0)_{B_r \times d}\), \(\ell_i^{(0)} = (0)_{B_r}\), \(m_i^{(0)} = (-\infty)_{B_r}\).
- for \(1 \le j \le T_c\) do
- Load \(K_j, V_j\) from HBM to on-chip SRAM.
- On chip, compute \(S_i^{(j)} = Q_i K_j^\top \in \mathbb{R}^{B_r \times B_c}\).
- On chip, compute \(m_i^{(j)} = \max\!\left(m_i^{(j-1)},\ \text{rowmax}(S_i^{(j)})\right) \in \mathbb{R}^{B_r}\), \(\tilde{P}_i^{(j)} = \exp\!\left(S_i^{(j)} - m_i^{(j)}\right) \in \mathbb{R}^{B_r \times B_c}\) (pointwise), \(\ell_i^{(j)} = e^{\,m_i^{(j-1)} - m_i^{(j)}} \ell_i^{(j-1)} + \text{rowsum}(\tilde{P}_i^{(j)}) \in \mathbb{R}^{B_r}\).
- On chip, compute \(O_i^{(j)} = \text{diag}\!\left(e^{\,m_i^{(j-1)} - m_i^{(j)}}\right) O_i^{(j-1)} + \tilde{P}_i^{(j)} V_j\).
- end for
- On chip, compute \(O_i = \text{diag}\!\left(\ell_i^{(T_c)}\right)^{-1} O_i^{(T_c)}\).
- On chip, compute \(L_i = m_i^{(T_c)} + \log\!\left(\ell_i^{(T_c)}\right)\).
- Write \(O_i\) to HBM as the \(i\)-th block of \(O\).
- Write \(L_i\) to HBM as the \(i\)-th block of \(L\).
- end for
- Return the output \(O\) and the logsumexp \(L\).
Reading the algorithm with what we’ve built. Every line maps onto something we’ve already derived. The paper’s notation lines up with the blog’s as follows: \(S_i^{(j)}\) is our score tile \(x_i\), \(\ell\) is our denominator \(d_i'\), \(m_i^{(j)}\) is our running max \(m_i\), \(\tilde{P}\) is the unnormalized \(e^{x_i - m_i}\) term, and \(O_i^{(j)}\) is our running output \(o_i'\). The superscript \((j)\) is the inner-loop step.
- Lines 1 and 2 are the tiling setup: \(Q\) is cut into \(T_r\) row blocks of size \(B_r\), and \(K, V\) into \(T_c\) row blocks of size \(B_c\), the two tile sizes from the Q-tiling and K/V-tiling steps above.
- Line 3 iterates over query blocks; line 6 iterates over key/value tiles. The hardware actors behind these loops, one independent thread block per query block, a warp-cooperative sweep inside, were covered in the mapping subsection.
- Lines 4, 7 are the GMEM → SRAM loads: one Q block once per outer iteration, one K and V block per inner step.
- Line 8 is the first matmul, \(S = QK^\top\), producing a \(B_r \times B_c\) score tile.
- Line 9 is the online softmax, batched over \(B_r\) rows. The
rowmaxandrowsumhere are exactly the warp-reduced steps from the hardware mapping above: a row’s \(B_c\) score values are spread across warp lanes, so these reductions run as warp shuffles. \(\ell\) is the running denominator \(d_i'\), and its update is the same surrogate recurrence we derived. - Line 10 is the output recurrence. \(O_i^{(j)}\) is the running output \(o_i'\). The \(\text{diag}(e^{m^{(j-1)} - m^{(j)}})\) factor rescales the previous partial output when the max changes, and \(\tilde{P}_i^{(j)} V_j\) is the second matmul, \(P \times V\), adding the current tile’s contribution.
The one real difference: rescaling is deferred. Look closely at line 10 versus our earlier \(o_i'\) recurrence. Our recurrence divided by \(d_i'\) at every step. Algorithm 1 does not divide inside the inner loop. \(O_i^{(j)}\) is kept unnormalized throughout the sweep, rescaled only by the max-correction factor \(e^{m^{(j-1)} - m^{(j)}}\). The division by the denominator happens exactly once, on line 12, after the inner loop finishes: \(O_i = \text{diag}(\ell_i^{(T_c)})^{-1} O_i^{(T_c)}\).
This is the key FA1 → FA2 change. FA1 rescaled the output by the denominator on every inner step; FA2 moves that division out of the inner loop and applies it a single time at the end. The inner loop then contains only matmuls and the cheap max-correction, with the expensive per-step normalization removed. Fewer non-matmul operations on the hot path means the Tensor cores stay busier, and combined with the loop reordering (outer loop over query blocks, which parallelizes cleanly across thread blocks), this is most of where FA2’s speedup over FA1 comes from.
Line 13, the logsumexp. \(L_i = m_i^{(T_c)} + \log(\ell_i^{(T_c)})\) is only needed for the backward pass, where it lets the gradient recompute the softmax without storing the full probability matrix. Since this blog covers only the forward pass, we include \(L\) for completeness, to keep Algorithm 1 faithful to the paper, but we won’t use it further.
Note: in this section we only cover the forward pass, since inference is the main thing we want to cover. Training additionally needs the backward pass to propagate gradients and update parameters; for that, please refer to the paper.
References
CuTe DSL fundamentals and primitives
We’ve built the FlashAttention algorithm and tiled it for the GPU. From here on, every kernel we write (K1 through K8) will be written in CuTe Python DSL, the surface we use to express layouts, tensors, and Tensor-Core operations on Hopper. This section is the foundation: enough CuTe to read and understand the kernels that follow, built from first principles. Deep, kernel-specific mechanics (TMA hardware behavior, WGMMA fragment internals, swizzle and core-matrix details) are deferred to the kernel sections where they actually matter. Here we cover the abstractions.
We’ll go: what CuTe is and why it exists, then layouts, then tensors, then partitioning, then cute.gemm and cute.copy at a high level. Note: I initially added this part here, but it was very long, so I had to move it to a separate blog post to keep the content structured while still explaining most of it. So, pls refer to this CuTe DSL for the full in-depth ideas and understanding.
Experimental setup
Before getting into K1, two practical notes. All measurements in this worklog run on the same hardware and software stack (H100 SXM, fixed CuTe DSL and PyTorch versions, etc.), and all kernels are launched through a single shared harness with the same benchmark and correctness-check conventions. Rather than recapping that in the blog, the details live in the project README: hardware and software versions, the repo layout, the workload sweep (sequence lengths, head dims, causal flag), the tensor layout convention, and how to run any kernel from the command line.
The repo is at: GitHub.
We’ll introduce just enough of the harness inline when K1 lands (one example command, a one-line note on what CHECK=1 does, and what TFLOPS gets reported). From K2 onward, the same conventions apply unchanged. If anything in the setup is unclear while reading a kernel section, the README is the reference.
With that, on to K1.
K1: the naive baseline
The idea
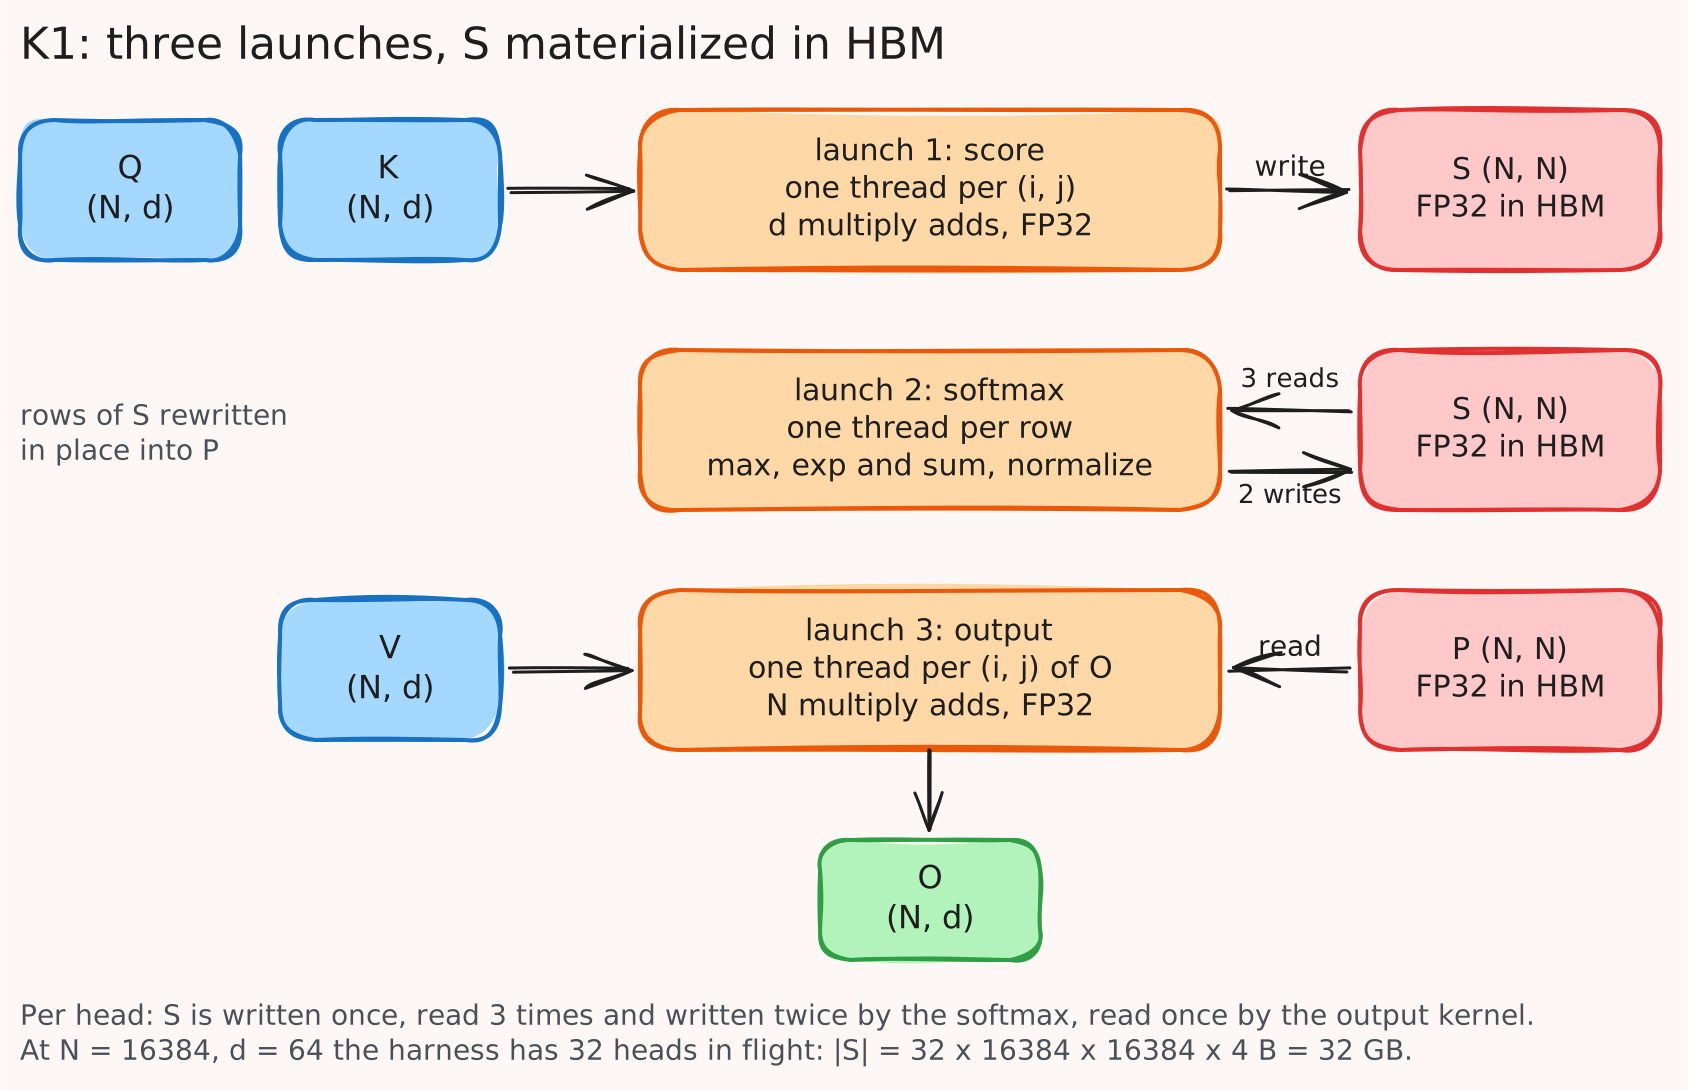
K1 is the attention math from the first section written down as literally as possible, with nothing from FlashAttention in it. Three kernel launches, one per equation:
\[S = \frac{QK^\top}{\sqrt{d}} \;\;(\text{masked if causal}), \qquad P = \text{softmax}(S), \qquad O = PV\]\(S\) is materialized in HBM in FP32, all \(B \times N \times N\) of it, and the softmax rewrites it in place into \(P\). The point of K1 is not to be fast. It is to measure what the next seven kernels are worth, and to make the memory argument from the intro concrete on a real GPU.
What the code does
The three kernels live in kernels/k1.py. Each is a plain CUDA style kernel written in the DSL: block and thread indices, a bounds check, a scalar loop.
| Launch | Grid and block | One thread computes |
|---|---|---|
| Score | \((N/16,\ N/16,\ B)\) blocks of \(16 \times 16\) | \(S[i,j] = \sum_k Q[i,k]\,K[j,k] \cdot \tfrac{1}{\sqrt d}\), reading \(Q\) and \(K\) from HBM, FP32 accumulate; writes \(-\infty\) when causal and \(j > i\) |
| Softmax | \((N/256,\ B)\) blocks of 256 | one full row of \(S\): pass 1 row max, pass 2 exponentiate and sum, pass 3 multiply by the reciprocal; in place |
| Output | \((d/16,\ N/16,\ B)\) blocks of \(16 \times 16\) | \(O[i,j] = \sum_k P[i,k]\,V[k,j]\) over the full row of \(P\) |
Two DSL details are worth seeing once, because every later kernel relies on them. The causal flag and the head dimension are JIT time constants: the mask branch is compiled in or out rather than tested at run time, and the \(d\) long dot product is unrolled into straight line multiply adds. The mechanics of that specialization are in the CuTe post under JIT specialization. Everything else in K1 is what you would write in CUDA C.
The \(S\) buffer is allocated once per configuration, at compile time, not per launch. At \(N = 16384\) and \(d = 64\) there are 32 heads times batches in flight, so
\[|S| = 32 \times 16384 \times 16384 \times 4\ \text{bytes} = 32\ \text{GB}\]which fits on the 80 GB card only because the harness keeps the total token count fixed at 16384 as \(N\) grows. The intro’s 4 TB figure for a million tokens is this same product with \(N = 10^6\) and one head.
How the numbers are measured
Every kernel in this worklog is run the same way, so here it is once. The harness folds heads into the batch dimension, sweeps sequence length \(N \in \{512, \ldots, 16384\}\) at a fixed 16384 total tokens, head dimension \(d \in \{64, 128\}\) with a 2048 wide hidden size (so 32 or 16 heads), and causal on or off. It compiles once per configuration, runs 10 warmup and 30 timed iterations with CUDA events, and reports the mean. TFLOPS uses the standard forward count
\[\text{FLOPs} = 4 \cdot B \cdot N^2 \cdot H \cdot d \quad (\text{halved for causal})\]so causal kernels are credited only for the triangle they need to compute, whether or not they skip the rest. With CHECK=1 the output is compared against PyTorch’s math backend run in FP32 on exactly the inputs the kernel consumed, chunked over the batch so the reference never materializes more than it needs to. An element is bad when its error exceeds \(10^{-2}\) absolute plus \(10^{-2}\) relative. One run of one configuration:
CHECK=1 SEQLEN=4096 HEADDIM=64 CAUSAL=0 python bench.py k1
Hardware and software for every number in this post: H100 SXM 80 GB HBM3 on a rented node, driver 595.91, nvidia-cutlass-dsl 4.5.1, PyTorch 2.6.0 with CUDA 12.4, inside a container with no clock locking available. The node is power capped at 500 W, which matters once the tensor cores are in use; the K4 section quantifies it. The full table is in the repo README.
Numbers
K1 passes the check on all 24 configurations (zero bad elements, maximum absolute error \(3.9 \times 10^{-3}\), which is BF16 output rounding). Throughput in TFLOPS:
| causal | \(d\) | 512 | 1024 | 2048 | 4096 | 8192 | 16384 |
|---|---|---|---|---|---|---|---|
| 0 | 64 | 1.10 | 1.10 | 1.10 | 1.10 | 1.03 | 0.98 |
| 0 | 128 | 0.96 | 0.98 | 1.00 | 1.01 | 1.01 | 1.00 |
| 1 | 64 | 0.61 | 0.66 | 0.67 | 0.67 | 0.67 | 0.68 |
| 1 | 128 | 0.71 | 0.68 | 0.69 | 0.72 | 0.72 | 0.72 |
At \(N = 16384\), \(d = 64\), one call takes 2245 ms non causal and 1623 ms causal. The dense BF16 peak of the H100 SXM is 989 TFLOPS, so K1 sits at a tenth of one percent of it.
Timing the three launches separately (tools/split_k1.py, a separate run, so the totals differ slightly from the sweep) says where it goes:
| \(N = 16384\) | score | softmax | output | total |
|---|---|---|---|---|
| \(d = 64\), non causal | 1285 ms | 78 ms | 775 ms | 2138 ms |
| \(d = 128\), non causal | 1291 ms | 40 ms | 774 ms | 2104 ms |
| \(d = 64\), causal | 621 ms | 76 ms | 707 ms | 1404 ms |
The two matmul launches take 95 percent of the time. The softmax, which is the only launch that touches \(S\) in a streaming pattern, moves its 5 passes over 34 GB in 78 ms, about 2.2 TB/s, so it alone runs near the HBM limit. Under the causal mask the score launch halves (the masked half writes a constant and skips the dot product) but the output launch still walks full rows of \(P\), which is why causal is only a third faster overall.
Notes
- Flat in \(N\), flat in \(d\). Nothing is reused, so nothing gets cheaper with size. Every multiply add is paired with its own loads, the arithmetic intensity is the 1 FLOP per element from the tiling section, and the kernels are bound by load latency, not by HBM bandwidth. The traffic on \(S\) alone (seven passes over 32 GB) would take about 70 ms at the 3.35 TB/s HBM rate; the measured 2245 ms is thirty times that.
- Causal is slower than it should be. The score kernel still visits every \((i, j)\) and writes \(-\infty\) for the masked half, and the softmax and output kernels still walk full rows. Time drops by 30 percent while the credited FLOPs halve, which is why the causal rows show lower TFLOPS. Skipping the masked tiles outright needs tiling, which is K2.
- The memory footprint is the real verdict. 32 GB of scratch for a 16k context at one head, growing with \(N^2\). The whole rest of this worklog is about never allocating that buffer.
References
- FlashAttention paper, Dao et al., section 2.2 for the standard attention algorithm as three passes over HBM
- NVIDIA H100 datasheet for the 989 TFLOPS dense BF16 and 3.35 TB/s figures
K2: tiled online softmax
The idea
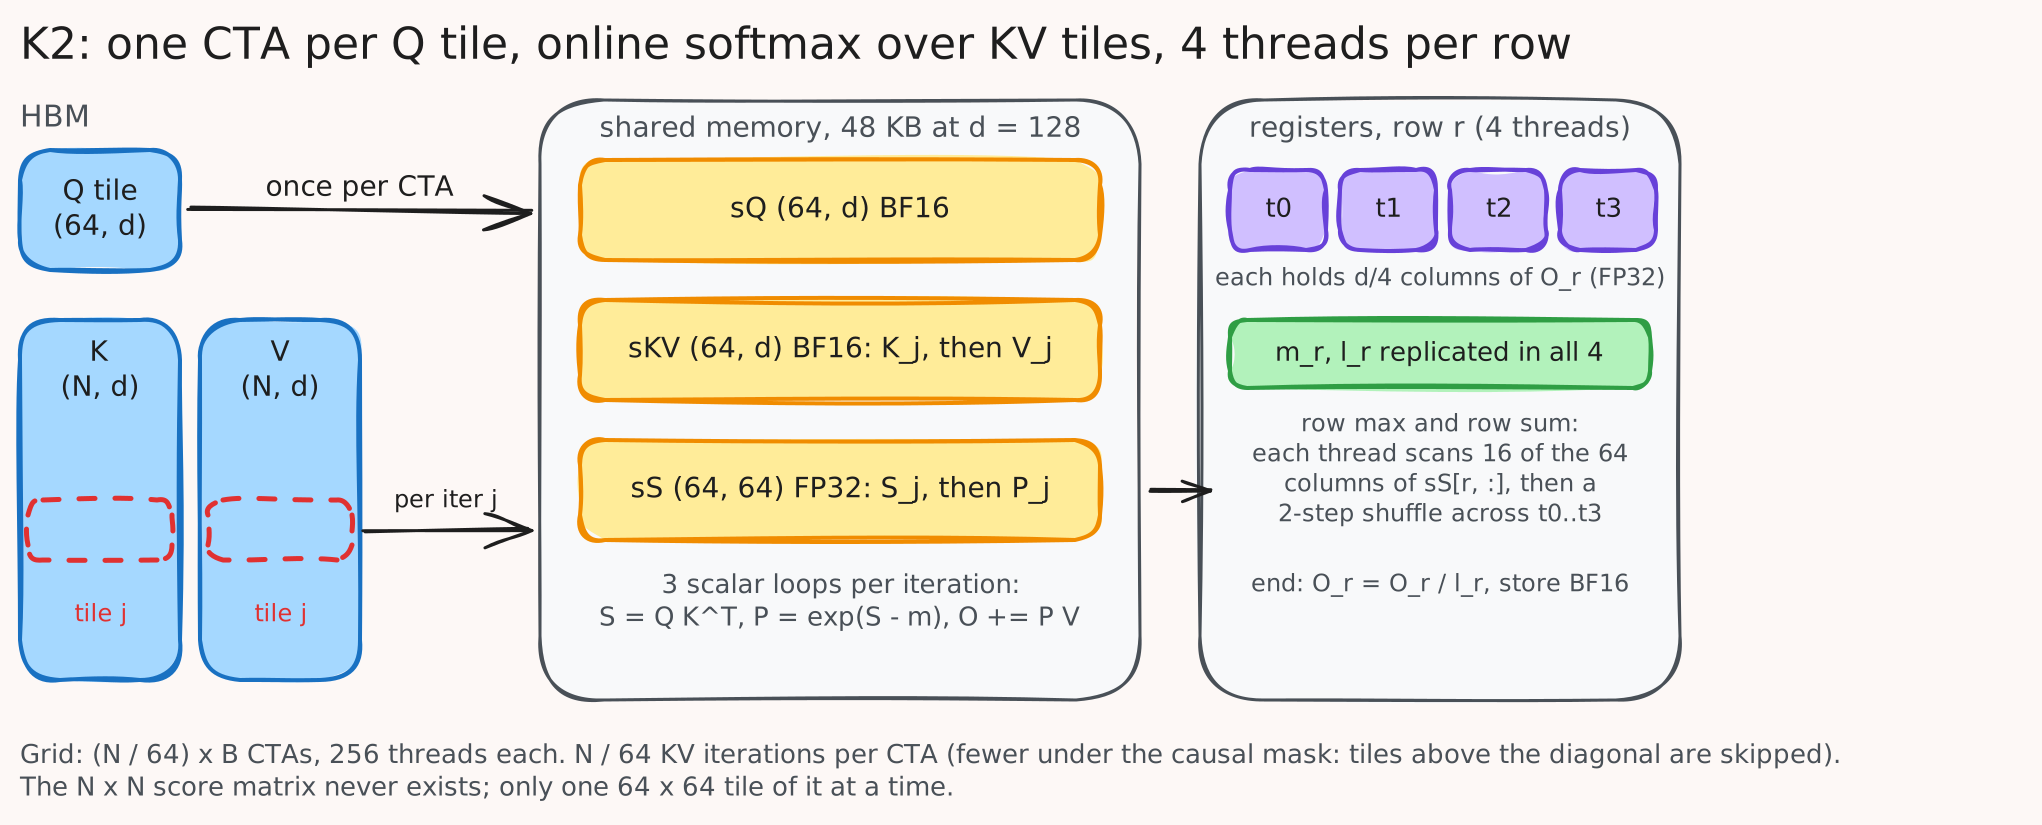
K2 is Algorithm 1 from the FA2 section, written as one kernel. A thread block takes one tile of \(B_r = 64\) query rows, keeps it in shared memory for the whole kernel, and walks the keys and values \(B_c = 64\) rows at a time. For each KV tile it forms the \(64 \times 64\) score tile in shared memory, folds it into the running max and sum per row, exponentiates it in place into \(P\), and accumulates \(P V_j\) into an output block held in registers. The \(N \times N\) matrix never exists; one \(64 \times 64\) tile of it does, and it is overwritten 256 times at \(N = 16384\).
Nothing in K2 uses a Hopper feature. Loads are ordinary per-thread loads, the matmuls are scalar FP32 loops, and the only cooperation between threads is a block barrier between phases and a shuffle inside the row groups. That is deliberate: K2 is the algorithm, and K3 to K8 are what the hardware adds to it.
What changed from K1
The kernel is kernels/k2.py, one class, one launch of \((N / 64) \times B\) blocks of 256 threads.
- One kernel, three phases. Load the Q tile once, loop over KV tiles, divide by the row sum and store. Inside the loop: load \(K_j\), score tile, softmax update, load \(V_j\) into the same buffer, accumulate.
- The thread to row mapping. 256 threads over 64 rows gives four threads per row. The four split the row’s output columns (\(d / 4\) FP32 registers each), scan the row’s 64 scores in stride-4 slices for the max and the sum, and exchange their partials with two
shfl.xorsteps, so the running max and sum live replicated in all four threads’ registers and never touch shared memory. The reduction primitive is described in the CuTe post under warp reductions; shared memory as acute.structunder shared memory. - Shared memory: 48 KB at \(d = 128\). sQ (\(64 \times d\) BF16), one buffer reused for \(K_j\) then \(V_j\), and sS (\(64 \times 64\) FP32). Plain row major layouts, no swizzle.
- Deferred normalization. The accumulator is rescaled by \(e^{m_{\text{old}} - m_{\text{new}}}\) when the row max moves and divided by the row sum once at the end, exactly the FA1 to FA2 change from the algorithm section.
- Causal: skip, then mask. The loop runs only over the KV tiles a Q tile can see, \(\lfloor (q_0 + 63) / 64 \rfloor + 1\) of them, and masks per element inside the one tile that straddles the diagonal. K1 had no tiles to skip.
The arithmetic per iteration and per thread, from the loop bounds: 16 scores of \(d\) multiply adds each, then \(d / 4\) output columns of 64 multiply adds each. At \(d = 128\) that is 4096 FMAs per thread per tile, all scalar FP32, all reading shared memory.
Numbers
K2 passes the check on all 24 configurations with zero bad elements, on uniform and on sharp attention data. TFLOPS:
| causal | \(d\) | 512 | 1024 | 2048 | 4096 | 8192 | 16384 |
|---|---|---|---|---|---|---|---|
| 0 | 64 | 10.8 | 11.1 | 10.3 | 9.7 | 8.8 | 8.3 |
| 0 | 128 | 5.0 | 5.1 | 5.2 | 5.2 | 5.2 | 5.1 |
| 1 | 64 | 8.9 | 9.8 | 10.3 | 10.6 | 9.9 | 9.2 |
| 1 | 128 | 4.5 | 4.7 | 4.9 | 5.0 | 5.0 | 5.1 |
At \(N = 16384\), \(d = 64\): 265 ms non causal against K1’s 2245 ms, 120 ms causal against 1623 ms. The time halves under the causal mask now that the masked tiles are skipped, while K1 only lost 30 percent.
Notes
- A loop that looked free cost 2.3x. The first version of this kernel unrolled the two 16-element row scans with
range_constexpr, the same construct every other loop in the kernel uses. It ran at 4.1 TFLOPS instead of 9.5, and 6.7x slower under the causal mask. The compiled binary says why: the kernel was already at the 255 register cap, and the unrolled scans added 1080 bytes of stack spills per thread at \(d = 64\) (1832 at \(d = 128\)) against 352 with ordinary runtime loops. The two versions are in the repo history; the shipped one keeps the runtime loops and a comment. Lesson for the rest of the worklog: in a register-starved scalar kernel, the DSL’s unrolling is a resource decision, not a free one, and the cubin is the only place to see it. - One CTA per SM, by registers. 255 registers times 256 threads is the whole register file, so each SM holds 8 warps of K2 regardless of its 48 KB of shared memory. The scalar FP32 loops run at a few FLOPs per cycle per warp with no latency hiding beyond those 8 warps; that is where the single digit TFLOPS come from.
- The win over K1 is structural, not clever. No scratch matrix in HBM, every K and V element read once per Q tile, and the output never leaves registers until the end. The kernel is still a few percent of the tensor core peak, because nothing in it is a tensor core instruction yet.
References
- FlashAttention-2 paper, Dao, Algorithm 1
- PTX ISA: shfl.sync for the butterfly reduction inside a row group
K3: TMA loads and an mbarrier pipeline
The idea
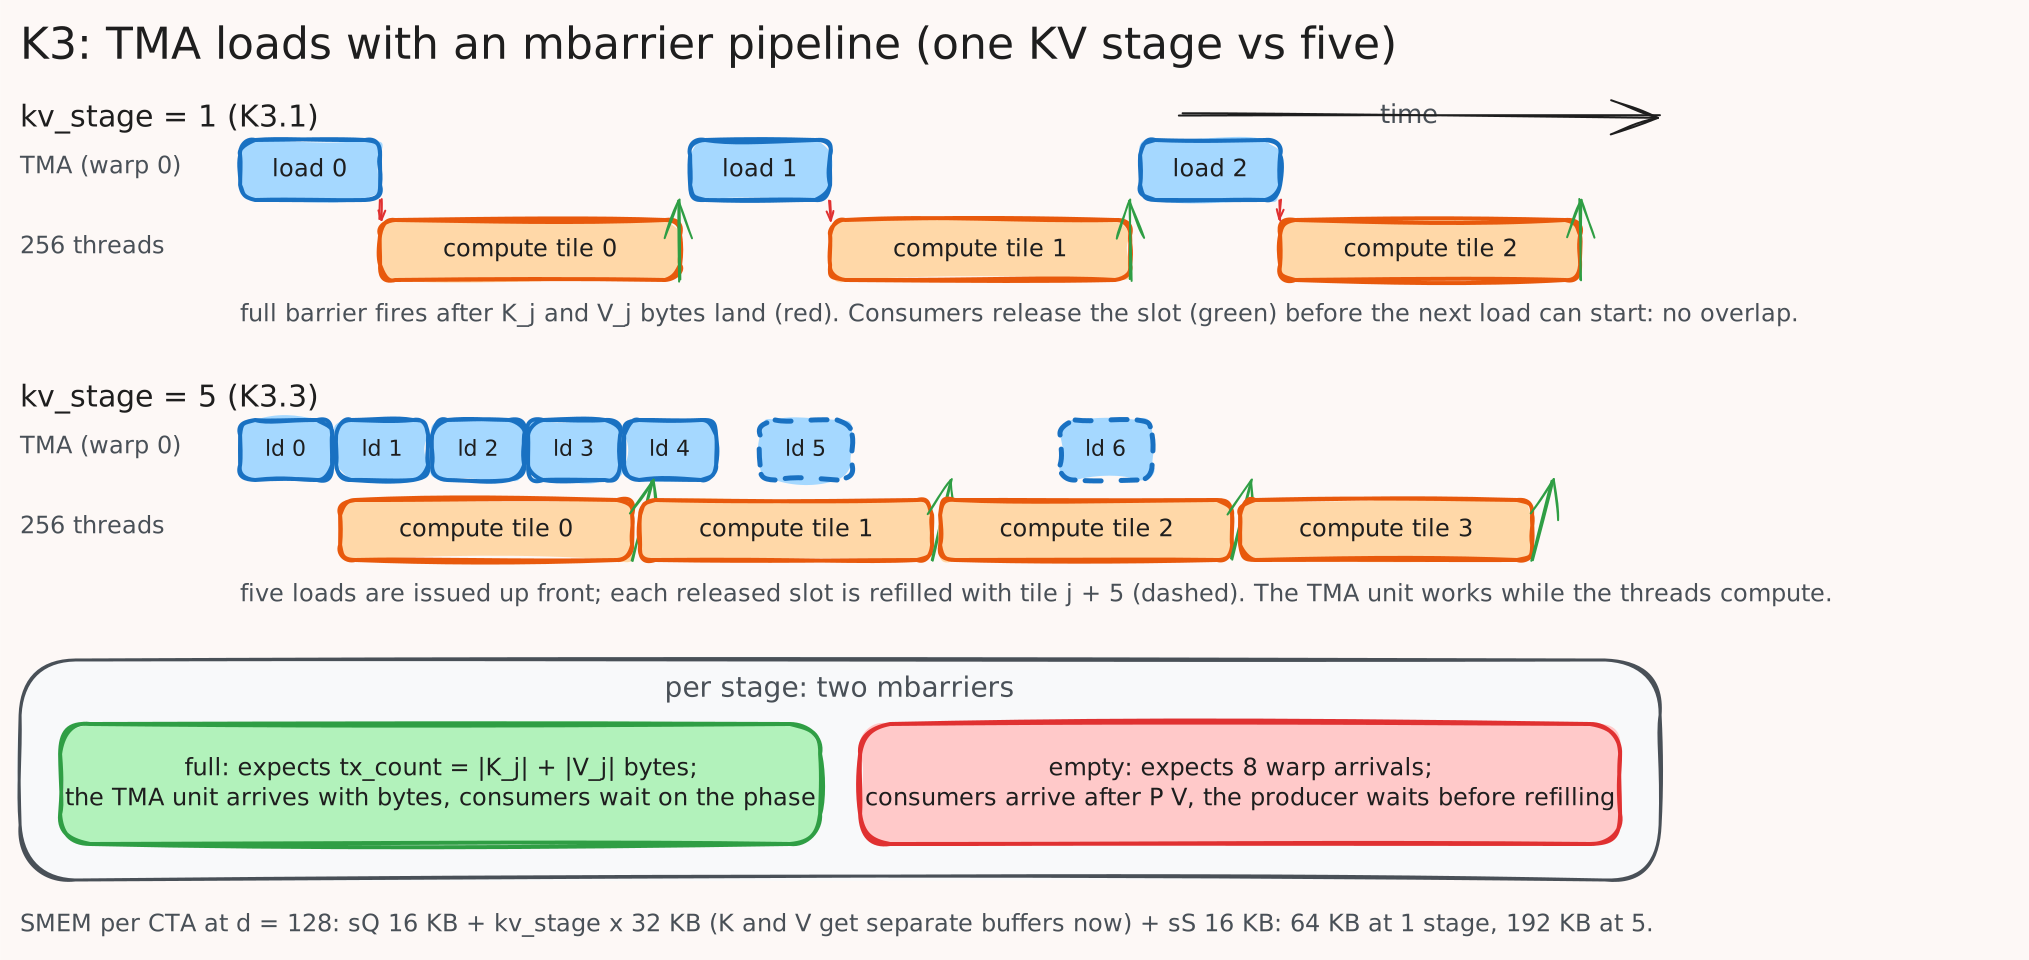
K2 spends its threads on two jobs that have nothing to do with each other: moving tiles from HBM into shared memory, and doing arithmetic on them. Every load is 256 threads each fetching two bytes at a time, with a block-wide barrier at the end, and while that happens no arithmetic is in flight. Hopper has a unit for the first job. The Tensor Memory Accelerator (TMA) takes a descriptor of a tensor in global memory and a tile coordinate, and copies the whole tile into shared memory on its own, with one thread issuing the instruction and nobody waiting for it. Completion is signalled by the hardware arriving on a memory barrier with the number of bytes it delivered.
That changes the structure of the kernel. Loads become asynchronous events that the compute side waits on, and once they are asynchronous, several can be in flight: give the K and V tiles a ring of kv_stage slots in shared memory, issue the loads for the next tiles while the current one is being consumed, and refill each slot as soon as the consumers release it. K3 builds exactly that machinery, and nothing else: the compute body is K2’s, unchanged. The three variants K3.1, K3.2 and K3.3 run the same code with a ring of 1, 2 and 5 slots.
What changed from K2
The kernel is kernels/k3.py, with k3_1.py, k3_2.py and k3_3.py selecting the depth. Line by line it is K2 with the load loops removed and the following put in their place. The primitives themselves (descriptors, transaction counts, the pipeline object and its two states) are explained in the CuTe post under TMA, mbarriers and pipelines; here is what K3 does with them.
- One thread issues every load. Warp 0 prefetches the three tensor descriptors once, issues the Q tile once, and issues K and V for each KV tile. The other 255 threads never touch global memory again until the output store.
- K and V get separate shared memory. K2 reused one buffer for K then V inside an iteration because its loads were synchronous. With loads in flight, tile \(j+1\)’s K can be landing while tile \(j\)’s V is still being read, so they cannot share bytes. One slot is now \(2 \cdot B_c \cdot d\) elements.
-
One barrier per slot covers both tiles. The slot’s full barrier expects $$ K_j + V_j \(bytes, both copies target it, and it fires only when both have arrived. Set it to\) K_j $$ alone and the consumer races the V copy. - Prefetch, steady state, drain. Before the loop the producer fills \(\min(\text{kv\_stage}, n_{kv})\) slots. Each iteration the consumers wait on the slot’s full barrier, run the K2 body, arrive on its empty barrier, and the producer refills that slot with tile \(j + \text{kv\_stage}\) if one remains. The last \(\text{kv\_stage} - 1\) iterations find nothing left to issue.
- Two pipeline states per side. The producer and the consumers each carry an index into the ring and a running count. The index says which slot, the count says which tile of global memory, and the two differ once the ring wraps.
- Shared memory stays plain row major. Swizzling only pays for the access pattern of the tensor cores, which K3 does not use; it arrives with WGMMA in K4.
What each variant costs per CTA, from the compiled binaries (cuobjdump --dump-resource-usage on the cubin the DSL keeps with CUTE_DSL_KEEP=cubin). Shared memory is sQ + slots × (sK + sV) + sS; registers are per thread, and 256 threads at more than 128 registers each fill the SM’s 64K register file, so one CTA per SM is the rule here whatever the shared memory says.
| K3.1 (1 slot) | K3.2 (2 slots) | K3.3 (5 slots) | |
|---|---|---|---|
| \(d = 64\): shared memory | 40 KB | 56 KB | 104 KB |
| \(d = 64\): registers per thread, stack bytes | 199, 0 | 255, 312 | 255, 312 |
| \(d = 64\): CTAs per SM | 1 | 1 | 1 |
| \(d = 128\): shared memory | 64 KB | 96 KB | 192 KB |
| \(d = 128\): registers per thread, stack bytes | 252, 0 | 128, 16 | 128, 16 |
| \(d = 128\): CTAs per SM | 1 | 2 | 1 (shared memory) |
For comparison K2 compiles to 255 registers with 352 bytes of stack at \(d = 64\), so it too runs one CTA per SM.
Numbers
All three variants pass the check on all 24 configurations with zero bad elements. TFLOPS:
| kernel | causal | \(d\) | 512 | 1024 | 2048 | 4096 | 8192 | 16384 |
|---|---|---|---|---|---|---|---|---|
| K3.1 | 0 | 64 | 13.1 | 13.5 | 13.9 | 13.9 | 12.4 | 11.8 |
| K3.1 | 0 | 128 | 5.4 | 5.5 | 5.5 | 5.5 | 5.6 | 5.6 |
| K3.1 | 1 | 64 | 10.8 | 12.0 | 12.3 | 12.6 | 12.6 | 11.4 |
| K3.1 | 1 | 128 | 4.8 | 5.1 | 5.3 | 5.4 | 5.4 | 5.4 |
| K3.2 | 0 | 64 | 5.5 | 5.6 | 5.6 | 5.6 | 5.4 | 4.9 |
| K3.2 | 0 | 128 | 5.8 | 5.9 | 5.9 | 5.9 | 5.8 | 5.5 |
| K3.2 | 1 | 64 | 4.8 | 5.2 | 5.4 | 5.5 | 5.6 | 5.3 |
| K3.2 | 1 | 128 | 5.0 | 5.3 | 5.5 | 5.6 | 5.7 | 5.6 |
| K3.3 | 0 | 64 | 5.5 | 5.6 | 5.6 | 5.7 | 5.4 | 4.9 |
| K3.3 | 0 | 128 | 5.0 | 5.0 | 5.0 | 5.1 | 5.0 | 4.8 |
| K3.3 | 1 | 64 | 4.8 | 5.2 | 5.4 | 5.5 | 5.5 | 5.2 |
| K3.3 | 1 | 128 | 4.4 | 4.7 | 4.8 | 4.9 | 4.9 | 4.9 |
Notes
- The pipeline buys nothing here, and that is the point of measuring it. Take K3.1 at \(N = 16384\), \(d = 128\): 4096 CTAs, 256 KV tiles each, 396 ms, one CTA resident per SM on 132 SMs. That is about 50 microseconds of compute per tile per CTA. The tile it waits for is 32 KB; at the SM’s share of HBM bandwidth (3.35 TB/s over 132 SMs) that takes about 1.3 microseconds. The load is under three percent of the iteration, so there is nothing to hide.
- Why K3.2 and K3.3 are half of K3.1 at \(d = 64\). Not the pipeline. The multi-slot variants carry a second pipeline state, the prefetch loop and the refill branch, and in a kernel that is already at 199 registers per thread that pushes the compiler to the 255 cap with 312 bytes of spills per thread. The spill traffic is the 2x. At \(d = 128\) the compiler instead lands the multi-slot variants at 128 registers, two CTAs fit per SM, and they edge ahead of K3.1 by a few percent. A scalar kernel with 256 threads lives at the mercy of the register allocator either way, which is one more reason to hand the arithmetic to the tensor cores.
- Causal now pays off properly. Tiles entirely above the diagonal are skipped (K2 does this too), so causal time is close to half of non causal at the long end: 96 ms against 186 ms for K3.1 at 16k, \(d = 64\). The credited FLOPs halve as well, so the TFLOPS rows look similar; the time is what dropped.
- K3 is plumbing for K4. Once the consumer is a tensor core instruction that finishes a tile in a few microseconds, the ring is what keeps it fed. Running the protocol at depth 5 here, with the slow consumer, verified it before the fast one arrived.
References
- PTX ISA: cp.async.bulk.tensor and mbarrier for the TMA copy and transaction-count barrier semantics
- FlashAttention-3 paper, section 3.1, for producer and consumer roles around TMA
- CUTLASS CuTe DSL pipeline source for
PipelineTmaAsync
K4: WGMMA, the tensor cores take over
The idea
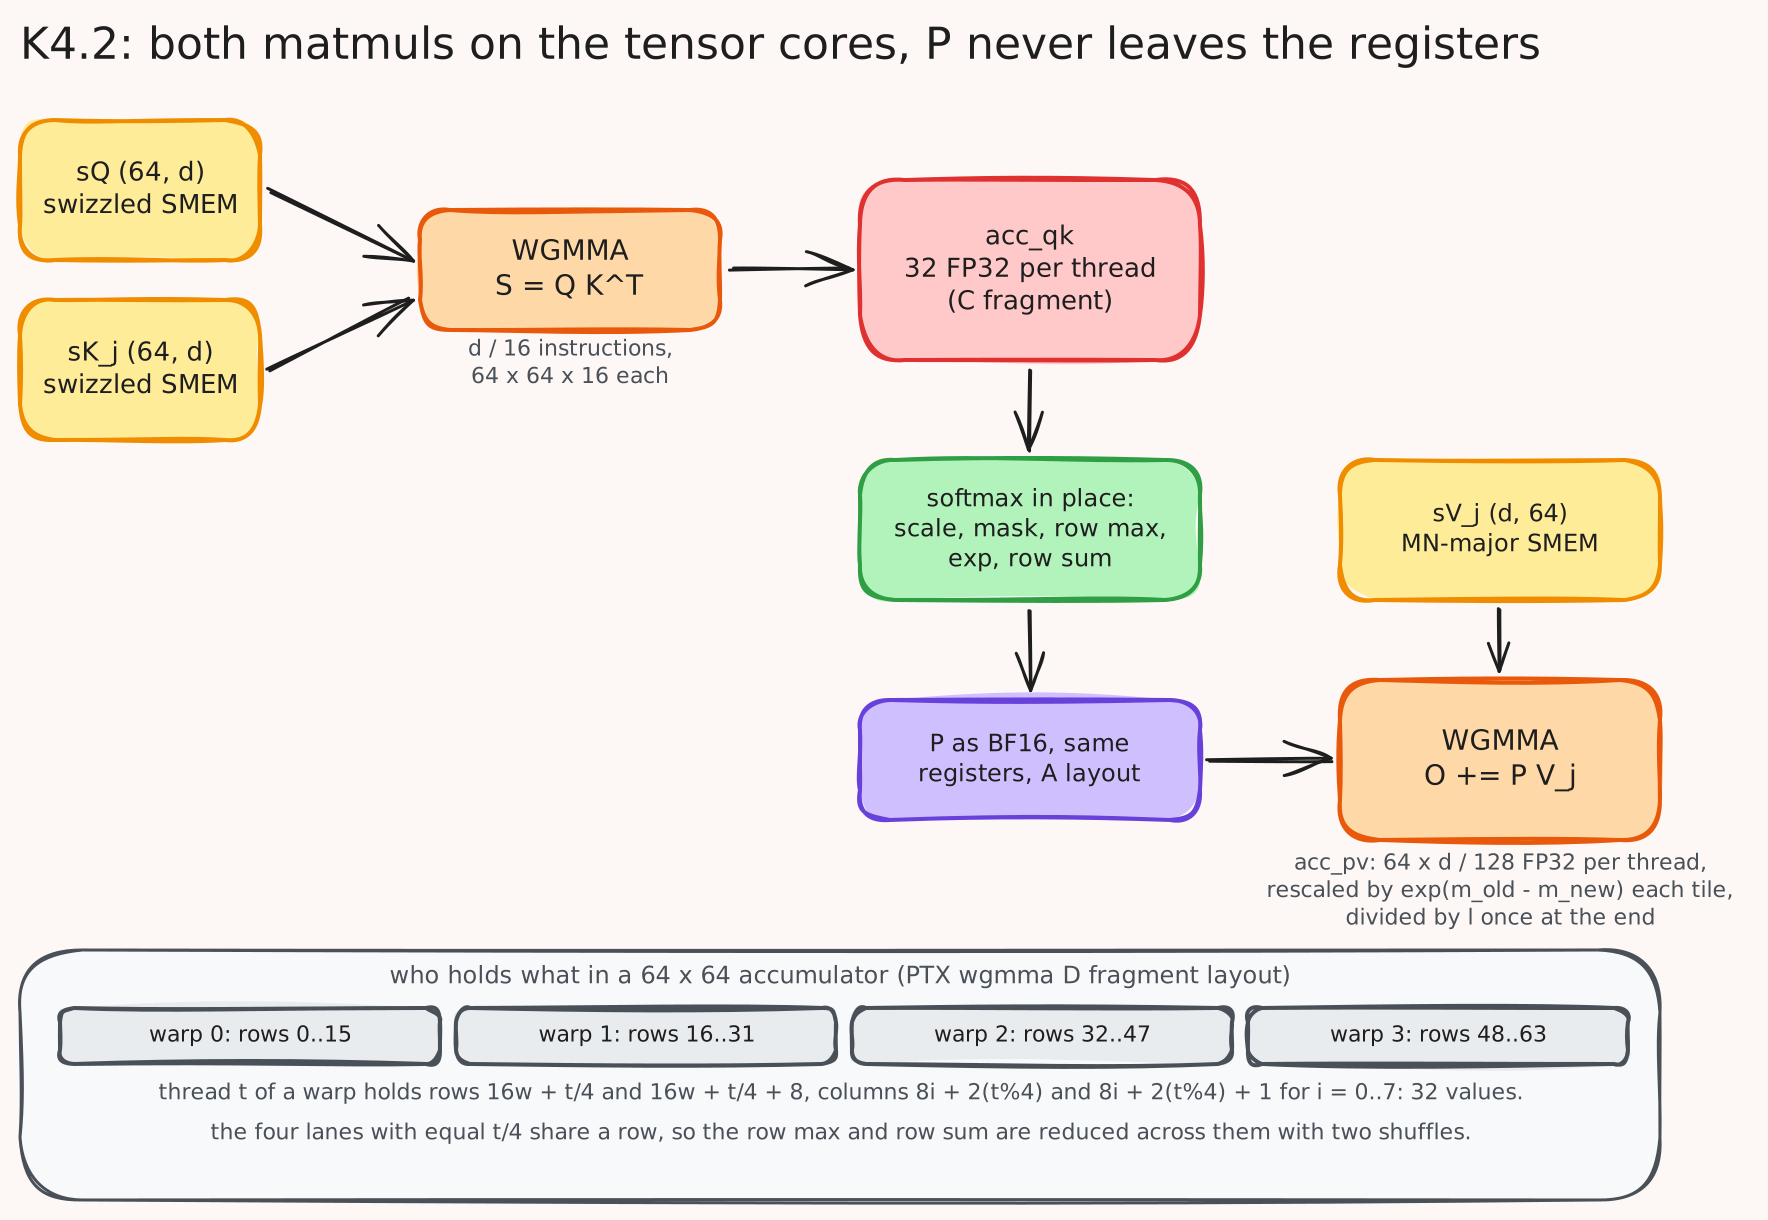
Everything up to here computes the two matmuls one multiply add at a time on the FP32 pipes. Hopper’s tensor core instruction, WGMMA, computes a \(64 \times N \times 16\) block product per issue for a whole warpgroup of 128 threads, reading its operands straight from shared memory through a descriptor and leaving the result spread across the warpgroup’s registers in a fixed pattern. One instruction replaces 16 iterations of K3’s inner loop for all 128 threads at once, and the operands never pass through registers on the way in.
The catch is the fixed pattern. The accumulator of a \(64 \times 64\) tile is 32 FP32 values per thread, and which rows and columns those 32 values belong to is decided by the hardware: two rows per thread, sixteen strided columns, with four threads sharing each row. Everything the softmax does (row max, exponentiate, row sum, rescale) has to be written against that pattern, and the result has to be handed to the second matmul as its A operand in the register layout that instruction expects. K4 does this in two steps so each can be checked on its own.
- K4.1 puts only \(S = QK^\top\) on the tensor cores and scatters the accumulator back into K3’s plain shared memory tile, where the K3 softmax and scalar PV run unchanged. It isolates the mechanics of issuing WGMMA, the swizzled operand layouts, and reading the accumulator with a coordinate probe.
- K4.2 keeps the accumulator where it is. The softmax runs on the fragment in registers, the exponentiated scores are cast to BF16 in place and reinterpreted as the A operand of the PV WGMMA, and the output accumulator persists in registers across all KV tiles.
What changed from K3
Kernels: kernels/k4_1.py and kernels/k4_2.py, with the fragment helpers shared in kernels/common.py. The primitives are in the CuTe post: swizzle, WGMMA, TV layouts and the register handoff.
- 128 threads. One warpgroup is the unit a WGMMA is issued by, so the CTA shrinks from 256 to 128 threads. The K3 pipeline is reused with 5 KV slots and the same producer, now warp 0 of the single warpgroup.
- Swizzled shared memory. The tensor cores read operands in 8 by 128 byte core matrices, and a plain row major tile would put every row’s chunk in the same banks. The sm90 helpers build the swizzled layout from the tile shape and dtype, and the TMA descriptor and the WGMMA descriptor are both derived from that one layout object, so producer and consumer agree by construction.
- K4.1: issue, then scatter. \(d / 16\) WGMMAs accumulate \(S\) (4 at \(d = 64\), 8 at \(d = 128\)), bracketed by a fence, a commit and a wait. An identity tensor partitioned the same way as the accumulator reports the \((m, n)\) coordinate of each fragment slot, and each thread writes its 32 values to that position in sS with the scale and the causal mask applied. From there the kernel is K3 with two threads per row instead of four.
- K4.2: softmax on the fragment. The per-row state becomes two values per thread (one per owned row), the row reductions are a loop over the thread’s 16 columns followed by two shuffles across the four row sharing threads, and the rescale multiplies the thread’s slice of the persistent output accumulator. The row sum is reduced across threads once, at the end.
- K4.2: the handoff. \(P\) is cast from FP32 to BF16 into a register tensor whose layout is the A operand layout of the PV instruction, aliased over the same registers as the accumulator view. For BF16 the two layouts put the same elements in the same thread, so the cast is the whole conversion. The A operand of the PV WGMMA then comes from registers while V comes from shared memory.
- V is re-viewed, not moved. For PV the contraction axis is the sequence axis, so V’s contiguous axis \(d\) is the N axis of the product, which makes V an MN-major operand. The kernel re-labels the V tensor’s modes at entry so that the layout helpers, the TMA tile and the MMA descriptor all see it that way. Same bytes in memory.
- Causal masking on the fragment. The coordinate probe gives each slot its absolute query and key index; the mask is applied only in tiles that straddle the diagonal, and tiles above it are skipped as before.
Numbers
Both kernels pass the check on all 24 configurations with zero bad elements, on uniform and on sharp attention data. TFLOPS:
| kernel | causal | \(d\) | 512 | 1024 | 2048 | 4096 | 8192 | 16384 |
|---|---|---|---|---|---|---|---|---|
| K4.1 | 0 | 64 | 6.2 | 6.3 | 6.4 | 6.4 | 6.4 | 6.2 |
| K4.1 | 0 | 128 | 3.5 | 3.5 | 3.5 | 3.6 | 3.6 | 3.6 |
| K4.1 | 1 | 64 | 5.5 | 5.8 | 6.1 | 6.1 | 6.2 | 6.2 |
| K4.1 | 1 | 128 | 3.1 | 3.3 | 3.4 | 3.4 | 3.5 | 3.5 |
| K4.2 | 0 | 64 | 229 | 277 | 310 | 328 | 331 | 308 |
| K4.2 | 0 | 128 | 202 | 251 | 282 | 299 | 312 | 310 |
| K4.2 | 1 | 64 | 142 | 200 | 244 | 274 | 291 | 302 |
| K4.2 | 1 | 128 | 131 | 184 | 228 | 259 | 278 | 288 |
Registers per thread from the compiled binaries, no spills in either: K4.1 128 (\(d = 64\)) and 165 (\(d = 128\)), K4.2 92 and 124.
A caveat on absolute numbers that applies from here on. The node runs at the H100 SXM’s full 700 W limit, but it runs hot: after an hour of sweeps the GPU idles at 80 to 84 C, and nvidia-smi dmon during a sustained tensor core kernel shows the SM clock falling from 1980 MHz to about 1.1 GHz within a few seconds at 300 W. The sweep numbers in this post are 30 timed iterations per configuration, a fraction of a second each, run in sequence, so they catch the GPU at whatever temperature the previous configuration left it; the same kernel measured at different points of the run moves by up to about 10 percent. That spread does not change any ordering between kernels, but it is why two numbers for the same kernel in this post can differ by a few percent, and why the comparison against the library kernels in the Results section is run differently: every kernel and baseline gets the same 45 second cooldown and the clock it ran at is recorded next to it.
Notes
- K4.1 is slower than K3.3 at \(d = 128\), and that is the right result. Moving \(QK^\top\) to the tensor cores removes roughly half of the scalar work, but the other half, \(PV\), is still a scalar loop, and it now runs on 128 threads instead of 256 with a 16 KB round trip through shared memory per tile on top. Amdahl’s law with the slow half left in place. The point of K4.1 is that it verified the WGMMA issue, the swizzle and the fragment coordinates in isolation; the number was never going to move until both matmuls left the FP32 pipes.
- K4.2 is a 40x step, and the softmax is now the thing to look at. From 4.9 to 308 TFLOPS at 16k is the tensor cores doing what they are built for. What remains between K4.2 and the 989 TFLOPS peak is everything that is not a WGMMA: the per-tile scale, mask, max, exp, rescale and sum on the fragment, the two shuffles per row, the casts, and the waits, all of which run with the tensor cores idle because this kernel issues its instructions in sequence. The next three kernels are about running those parts at the same time.
- Register use dropped by half. K4.2 holds its whole working set in 92 registers at \(d = 64\) where K3 needed 199 to 255: the accumulators are exactly the fragments the hardware defines, and the scalar loop temporaries are gone.
- Causal within a few percent of non causal. With the diagonal skip the causal kernel does half the tiles and masks one of them, so its TFLOPS (credited on half the FLOPs) sits close to the non causal figure. The earlier version of this kernel that masked every tile ran causal at about 60 percent.
References
- PTX ISA: asynchronous warpgroup level matrix instructions for the wgmma instruction, the accumulator fragment layouts and the fence, commit and wait semantics
- FlashAttention-3 paper, section 3, for the register-resident P handoff
- CUTLASS Hopper FMHA example in CuTe DSL for the fragment helpers this kernel reuses
K5: warp specialization
The idea
K4.2 still runs one instruction stream. Warp 0 issues the TMA loads for the next tiles in the gaps between its own WGMMAs and softmax work, and the whole warpgroup waits together on each barrier. Hopper’s answer is to split the CTA into warpgroups with different jobs: a producer warpgroup whose only work is to keep the shared memory ring full, and a consumer warpgroup that only computes. The producer runs ahead as far as the ring allows and blocks when every slot is in flight; the consumer never sees a load instruction. This is the structure FA3 is built on, and from here to K8 the CTA has at least one warpgroup that does nothing but move tiles.
Hopper adds one instruction for exactly this split. A warpgroup that only issues TMA needs a few dozen registers; a warpgroup holding attention accumulators wants every register it can get. setmaxnreg lets a warpgroup give registers back to the SM’s pool or take more from it after launch, so the producer runs at 24 registers per thread and the consumer at 240. Whether that knob matters depends on whether the consumer was short of registers to begin with, which K5 measures.
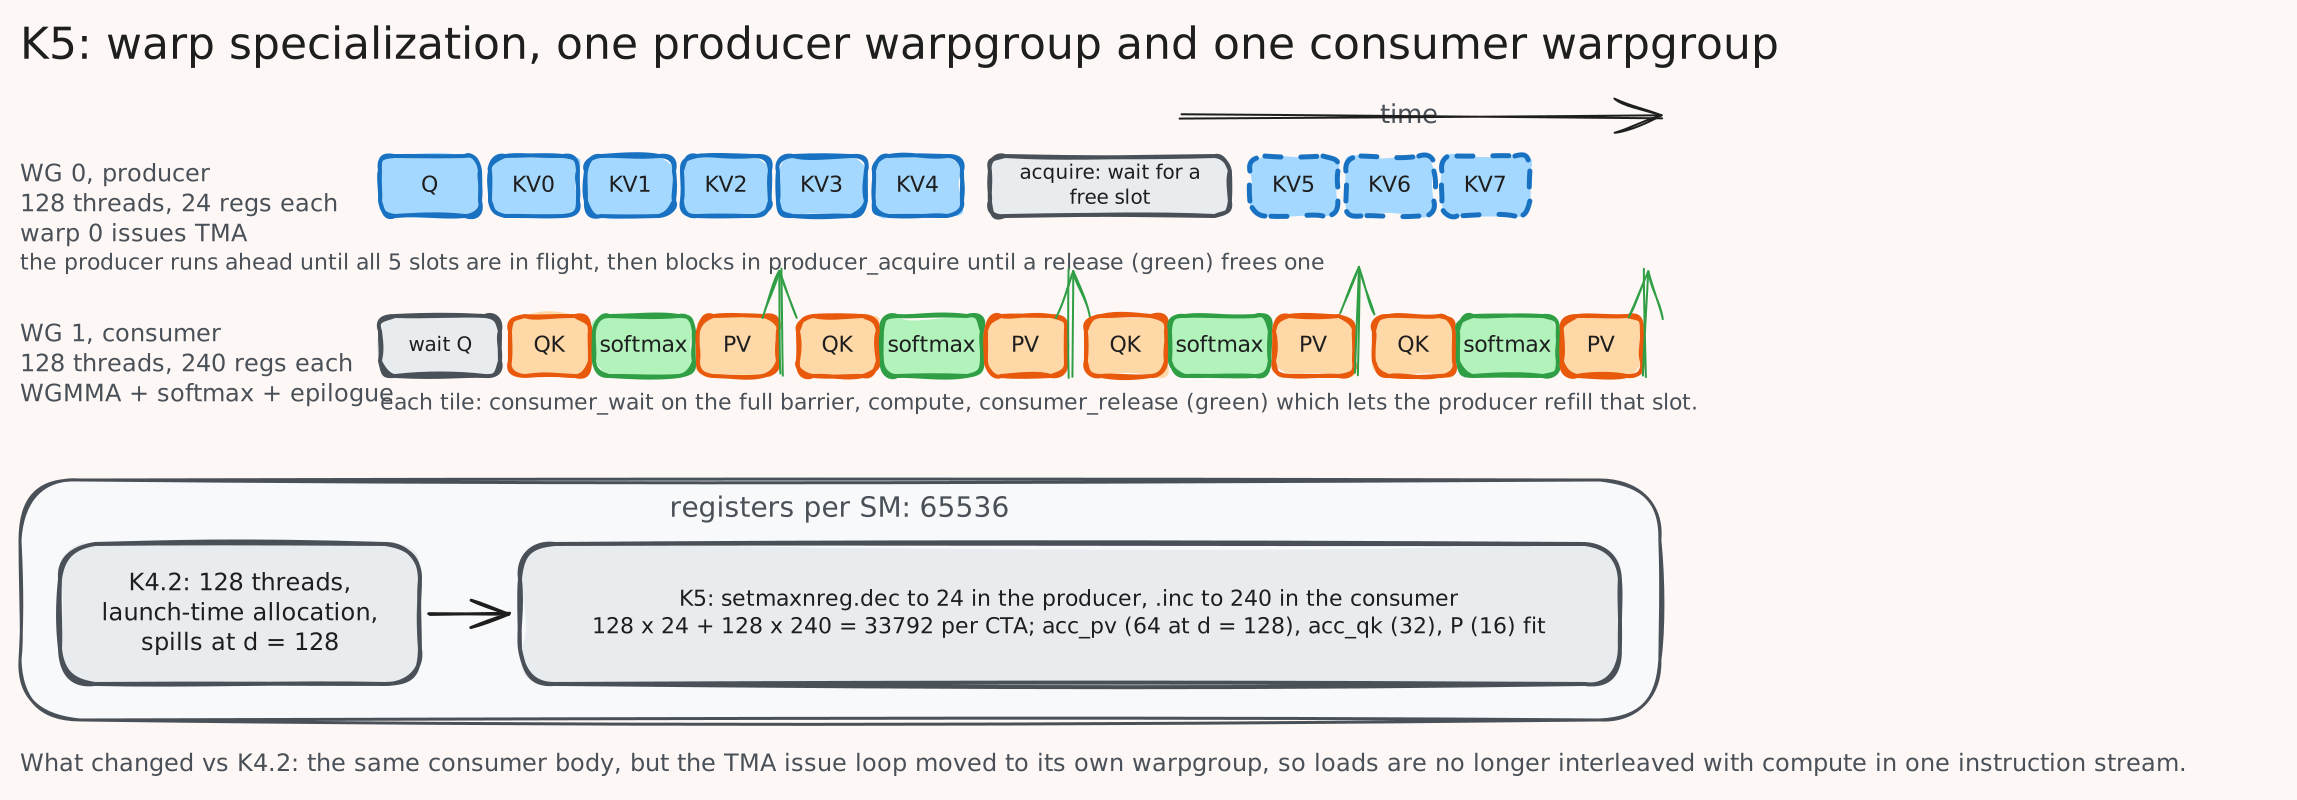
What changed from K4.2
Kernel: kernels/k5.py. The primitives are in the CuTe post under warp specialization.
- 256 threads, two roles. Threads 0 to 127 are the producer warpgroup; threads 128 to 255 are the consumer. The role is decided once from the warpgroup index and the two halves of the kernel body never meet again.
- The producer is a loop of loads. Warp 0 of the producer issues Q once, then issues K and V for every KV tile the Q tile needs, with
producer_acquireas the only wait. The other three producer warps do nothing; a warpgroup is the unit of register reallocation, so they are the price of the split. - The consumer is K4.2’s body, minus the refill. Same WGMMAs, same fragment softmax, same handoff, same epilogue. The trailing block that refilled a slot after
consumer_releaseis gone, because the producer does it. The thread index used for the MMA partitioning is the index within the warpgroup, not within the CTA. - Pipeline groups count warps of the consumer only. The consumer group of both pipelines is sized to four warps, the consumer warpgroup, not the whole CTA.
- Register reallocation is a flag.
REALLOC=1(the default) runs the producer at 24 registers and the consumer at 240;REALLOC=0leaves both at the launch allocation. Both were swept.
Numbers
K5 passes the check on all 24 configurations and on the sharp data. TFLOPS, with reallocation on and off:
| causal | \(d\) | 512 | 1024 | 2048 | 4096 | 8192 | 16384 | |
|---|---|---|---|---|---|---|---|---|
| 0 | 64 | on | 237 | 294 | 330 | 350 | 352 | 328 |
| 0 | 64 | off | 236 | 292 | 329 | 350 | 354 | 356 |
| 0 | 128 | on | 223 | 282 | 324 | 349 | 358 | 360 |
| 0 | 128 | off | 222 | 282 | 324 | 350 | 364 | 366 |
| 1 | 64 | on | 150 | 217 | 273 | 310 | 327 | 335 |
| 1 | 64 | off | 150 | 217 | 272 | 309 | 330 | 331 |
| 1 | 128 | on | 146 | 205 | 259 | 298 | 323 | 337 |
| 1 | 128 | off | 146 | 206 | 257 | 297 | 322 | 338 |
Against K4.2 at 16k: 328 vs 308 at \(d = 64\), 360 vs 310 at \(d = 128\).
Notes
- Six to sixteen percent, and that is honest. Taking the loads out of the consumer’s instruction stream is worth 6 percent at \(d = 64\) and 16 percent at \(d = 128\) here. K4.2 was not waiting on loads much to begin with, since the 5-slot ring already hid them; what K5 removes is the issue overhead and the barrier the whole warpgroup used to take together. The structural payoff of the split comes in K6, where a second consumer can share the producer.
- The register knob does nothing here, for a measured reason. The consumer compiles to 92 registers at \(d = 64\) and 124 at \(d = 128\) with no spills, well under the 128 per thread that 256 threads get by default, so raising its ceiling to 240 changes nothing and the runs with the knob off are within noise, sometimes a little ahead. The knob earns its keep when the consumer’s accumulators outgrow the default share: FA3’s \(128 \times d\) query tiles with two consumer warpgroups hold twice the output per thread that these \(64 \times d\) tiles do. The post keeps the knob on from K6 so the kernels match FA3’s structure; the number says it is not where the time is at this tile size.
- Three idle warps. Only one warp of the producer warpgroup issues anything. That is 96 threads parked for the kernel’s lifetime, and it is the normal shape of a Hopper warp-specialized kernel:
setmaxnregmakes them nearly free in registers, and the scheduler ignores warps that are blocked on a barrier.
References
- FlashAttention-3 paper, section 3.1, producer and consumer warpgroups
- PTX ISA: setmaxnreg for the register reallocation semantics
K6: ping-pong scheduling
The idea
With one consumer, the tensor cores idle while the softmax runs and the FP32 pipes idle while the WGMMAs run, because one warpgroup can only be doing one of them. Put two consumer warpgroups in the CTA, give them different Q tiles, and make them take turns: while A’s WGMMAs execute, B is in its softmax, and when A reaches its softmax, B issues. The two warpgroups run complete, independent pipelines; what the kernel adds is an ordering barrier that forces their WGMMA issue to alternate, which is what puts their softmax phases into the other’s matmul phases. The producer is shared: each K and V tile is loaded once and read by both consumers.
This is FA3’s ping-pong scheduling (their section 3.2). It is not a split of one tile’s work between two groups, which would not help because the softmax of a tile depends on that tile’s own scores. It is two pipelines offset in time so that the SM’s two kinds of units are busy at the same time.
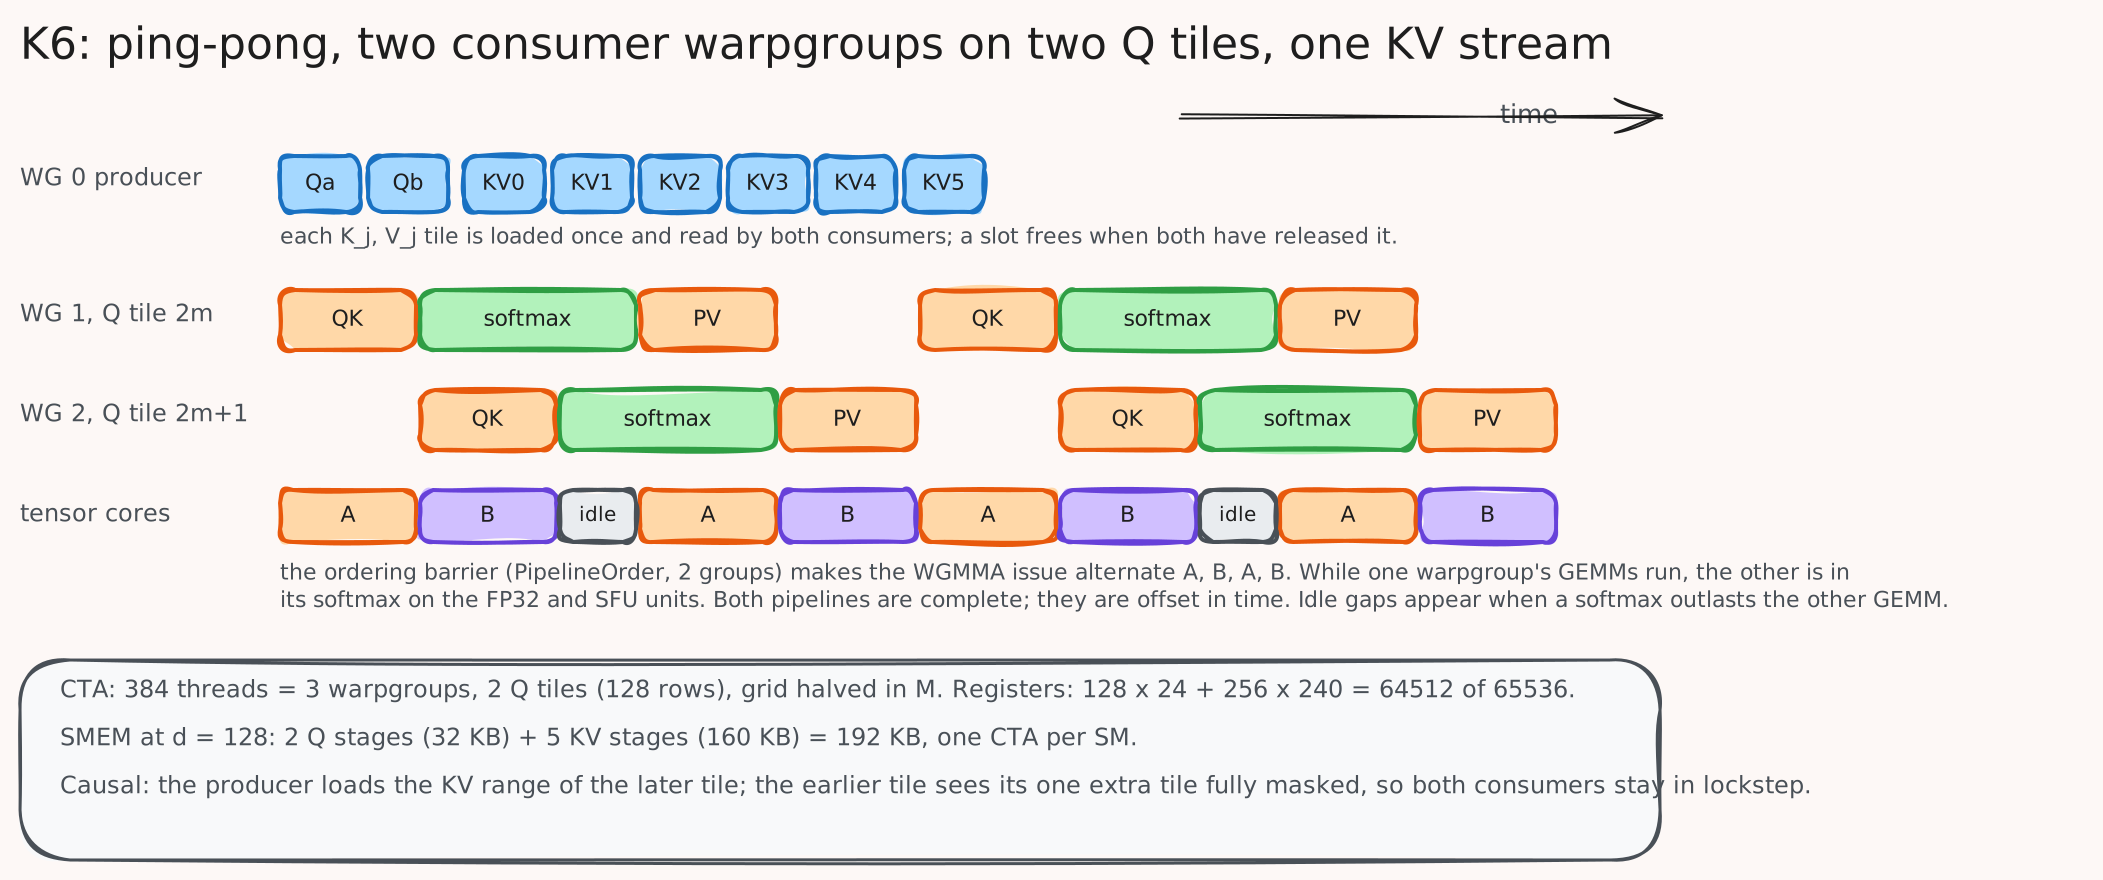
What changed from K5
Kernel: kernels/k6.py. The ordering primitive is in the CuTe post under pipeline order.
- 384 threads, three warpgroups. One producer, two consumers. Each CTA now owns 128 query rows (two \(64 \times d\) tiles), so the grid halves in the query dimension.
- Two Q slots, one KV ring. The producer loads Q tile \(2m\) into slot 0 and \(2m + 1\) into slot 1, then streams K and V once. The KV pipeline’s consumer group is sized to eight warps, so a slot is released only when both consumers have arrived on its empty barrier.
- The ordering barrier. A two-group
PipelineOrderwith depth one. Each consumer waits on it before the fence of a WGMMA batch and arrives after the commit, for the QK batch and again for the PV batch. Group A can issue first; from then on the issues alternate A, B, A, B. - Registers: 24, 240, 240. \(128 \times 24 + 256 \times 240 = 64512\) of the SM’s 65536, so this is the one configuration where the reallocation is doing real accounting. Shared memory at \(d = 128\) is 192 KB, one CTA per SM.
- Causal in lockstep. The producer loads the KV range of the later tile, which is at most one tile more than the earlier tile needs. The earlier tile sees that extra tile fully masked (every probability zero), so both consumers execute the same number of iterations and the barrier never waits on a group that has stopped.
Numbers
K6 passes the check on all 24 configurations and on the sharp data. TFLOPS:
| causal | \(d\) | 512 | 1024 | 2048 | 4096 | 8192 | 16384 |
|---|---|---|---|---|---|---|---|
| 0 | 64 | 214 | 274 | 313 | 338 | 351 | 334 |
| 0 | 128 | 281 | 377 | 456 | 506 | 500 | 501 |
| 1 | 64 | 136 | 202 | 261 | 304 | 332 | 347 |
| 1 | 128 | 178 | 273 | 364 | 437 | 487 | 502 |
Against K5 at 16k: 334 vs 328 at \(d = 64\) (2 percent), 501 vs 360 at \(d = 128\) (39 percent); causal 347 vs 335 and 502 vs 337.
Notes
- Why \(d = 128\) gains and \(d = 64\) barely does. The overlap window is the other consumer’s GEMM time. At \(d = 128\) each tile’s two WGMMA batches are 8 and 4 instructions of \(64 \times 64 \times 16\) and \(64 \times 128 \times 16\); at \(d = 64\) they are 4 and 4 of half the width, while the softmax work per tile is the same 32 values per thread either way. At \(d = 64\) the softmax is longer than the GEMM it is supposed to hide behind, so the tensor cores sit in the idle gaps the figure shows. FA3 reports the same shape of result, and its answer for the small head dimension is to pipeline within a warpgroup as well, which is the next step a longer worklog would take.
- Half the KV traffic per query row. Each K and V tile is read from HBM once per CTA and now serves 128 query rows instead of 64. At 16k and \(d = 128\) that halves the 8 MB of K and V each CTA streams per head. The kernel is not bandwidth bound, so this shows up as headroom rather than as time.
- Occupancy is one CTA per SM, by both registers and shared memory. Twelve warps per SM, of which eight compute. That is the Hopper shape: few fat warps with large register budgets, latency hidden by the asynchronous units rather than by warp count.
References
- FlashAttention-3 paper, section 3.2, ping-pong scheduling, and figure 3
- CUTLASS CuTe DSL pipeline source for
PipelineOrder
K7: FP8
The idea
| Hopper’s tensor cores run FP8 at twice the BF16 rate, and the operands are half the bytes. FA3’s FP8 path is K6 with Q, K and V stored as e4m3 (four exponent bits, three mantissa bits, largest value 448), the two matmuls issued as FP8 WGMMAs, and the accumulation still in FP32. Each input tensor carries one scale, $$s = \max | x | / 448\(, so that\)x / s$$ fits the format; the kernel undoes the scales on the way out. K7 is that, with nothing done about the quantization error, so that K8 can show what the error is and what fixes it. |
Two things in the kernel actually change, and both are layouts.
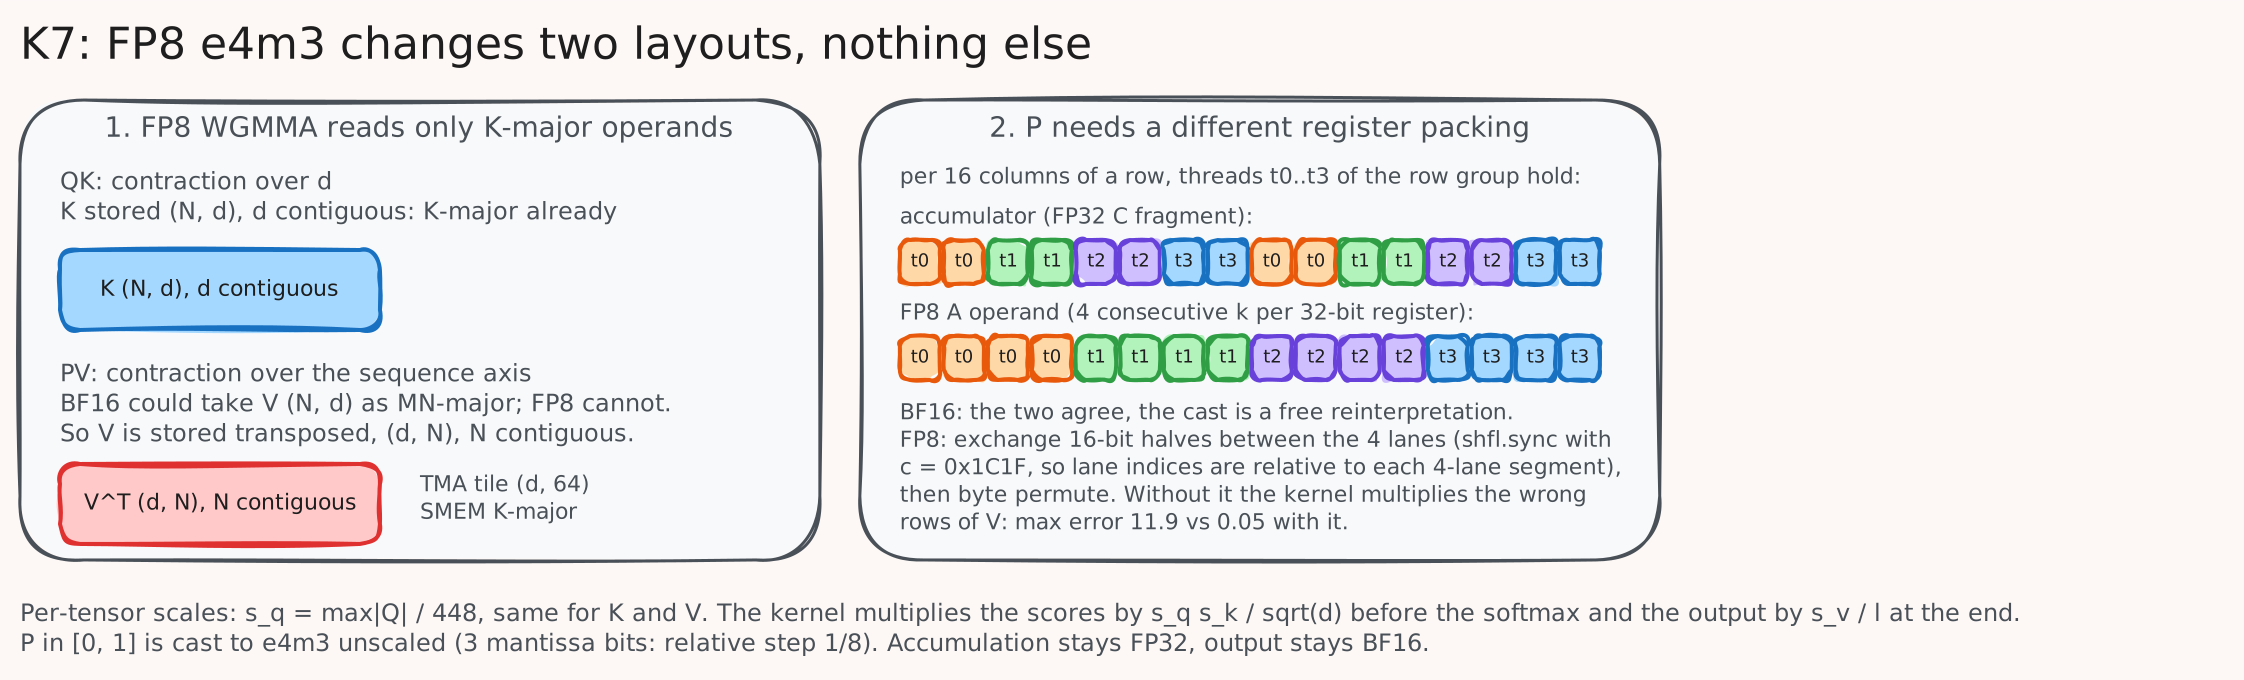
What changed from K6
Kernel: kernels/k7.py, the K6 structure with FP8 operands; the exchange lives in make_acc_into_op in kernels/common.py. The constraints are in the CuTe post under FP8.
- V is stored transposed. FP8 WGMMA accepts only K-major operands, the contraction index contiguous. For \(QK^\top\) the contraction is over \(d\) and K is already K-major. For \(PV\) the contraction is over the sequence axis, so V must be stored as \((d, N)\) with \(N\) contiguous. The harness does this transpose in preprocessing; FA3 does it inside the kernel with a shared memory transpose. The TMA tile for V becomes \((d, 64)\) and its shared memory layout is a K-major one built from the \(PV\) tile shape.
- The P handoff gets an exchange. Per 16 columns of a row, the accumulator gives thread \(t\) of the row group columns \(2t, 2t+1, 8+2t, 9+2t\); the FP8 A operand wants \(4t\) to \(4t+3\). The BF16 case had the same ownership on both sides and the cast was a reinterpretation; here the four lanes exchange 16-bit halves with
shfl.syncand reassemble registers withprmt. The shuffle’s fourth operand, 0x1C1F, makes the source lane index relative to each four-lane segment so the same code runs on all 32 lanes of a warp. Without this exchange the kernel multiplies \(P\) against the wrong rows of V. - Scales. The accumulator of the quantized \(QK^\top\) is smaller than the true scores by \(s_q s_k\), so the kernel multiplies by \(s_q s_k / \sqrt{d}\) before the softmax; the output is smaller by \(s_v\), folded into the final multiply by \(1 / l\). \(P\) itself is in \([0, 1]\) and is cast to e4m3 unscaled.
- Nothing else. Same warpgroups, same ordering barrier, same pipeline, same softmax.
Numbers
Correctness is checked two ways. Against an FP32 reference computed on the dequantized inputs, which isolates the kernel’s own error (the e4m3 rounding of \(P\) and the accumulation order), K7 has zero bad elements on all 24 configurations at a tolerance of \(10^{-1}\), with maximum errors of \(2 \times 10^{-2}\) on uniform data and \(5 \times 10^{-2}\) on sharp data. Against the exact FP32 attention on the unquantized inputs, which adds the input quantization error, the K8 section has the comparison. TFLOPS:
| causal | \(d\) | 512 | 1024 | 2048 | 4096 | 8192 | 16384 |
|---|---|---|---|---|---|---|---|
| 0 | 64 | 227 | 293 | 335 | 362 | 377 | 347 |
| 0 | 128 | 302 | 417 | 511 | 577 | 608 | 577 |
| 1 | 64 | 137 | 207 | 268 | 314 | 343 | 333 |
| 1 | 128 | 190 | 299 | 405 | 488 | 545 | 581 |
Against K6 at 16k: 347 vs 334 at \(d = 64\) (4 percent), 577 vs 501 at \(d = 128\) (15 percent).
Notes
- The exchange is not optional, and a flat test cannot tell you. With the exchange compiled out, the same kernel still passes a loose check on uniform data at long sequences: softmax over near-identical scores is nearly flat, the output collapses to the mean of V, and any permutation of \(P\) against V gives the same mean. On sharp attention data the difference is a maximum error of 11.9 against 0.05, with 80 percent of elements wrong. An earlier version of this project had dropped the segment-mask operand of the shuffle, concluded from a flat test that the exchange “made things worse”, and shipped without it. Test data has to make the kernel’s mistakes visible.
- Why 15 percent and not 2x. The tensor core rate doubles, the softmax does not. Every per-tile instruction that is not a WGMMA, scaling, masking, the max, the exponentials, the rescale, the sum, the cast and now the exchange, costs the same as in K6, and K6 was already spending a good part of each tile there. FA3 reaches its FP8 numbers with larger tiles and the intra-warpgroup pipelining that this worklog stops short of.
- Per-tensor scales are the weak point. One outlier sets the quantization step for the whole tensor. K8 is about that.
References
- FlashAttention-3 paper, section 3.3, FP8 layout constraints and the in-kernel V transpose
- PTX ISA: wgmma with FP8 operands and shfl.sync for the K-major requirement, the A fragment layout and the shuffle’s segment mask
K8: incoherent processing and block scales
The idea
| e4m3 has three mantissa bits. With one scale per tensor, the quantization step is $$\max | x | / 448$$ for every element, so a handful of large values decide how coarsely everything else is stored. Real attention inputs have exactly this shape: a few channels of Q and K carry activation outliers many times larger than the rest. K8 applies the two fixes FA3 uses. |
First, spread the energy before quantizing. Multiply Q and K by the same random sign matrix \(S\) and the normalized Hadamard matrix \(H\). Each rotated channel is a signed average of all original channels, so an outlier in one channel becomes a small contribution to all of them, and the scores do not change:
\[(QSH)(KSH)^\top = Q S H H^\top S K^\top = QK^\top \quad \text{since } S^2 = I,\ HH^\top = I\]Second, quantize per block rather than per tensor: one scale per \(64 \times d\) tile of Q and one per \(64 \times d\) tile of K, so an outlier can only coarsen the 64 rows it lives in.
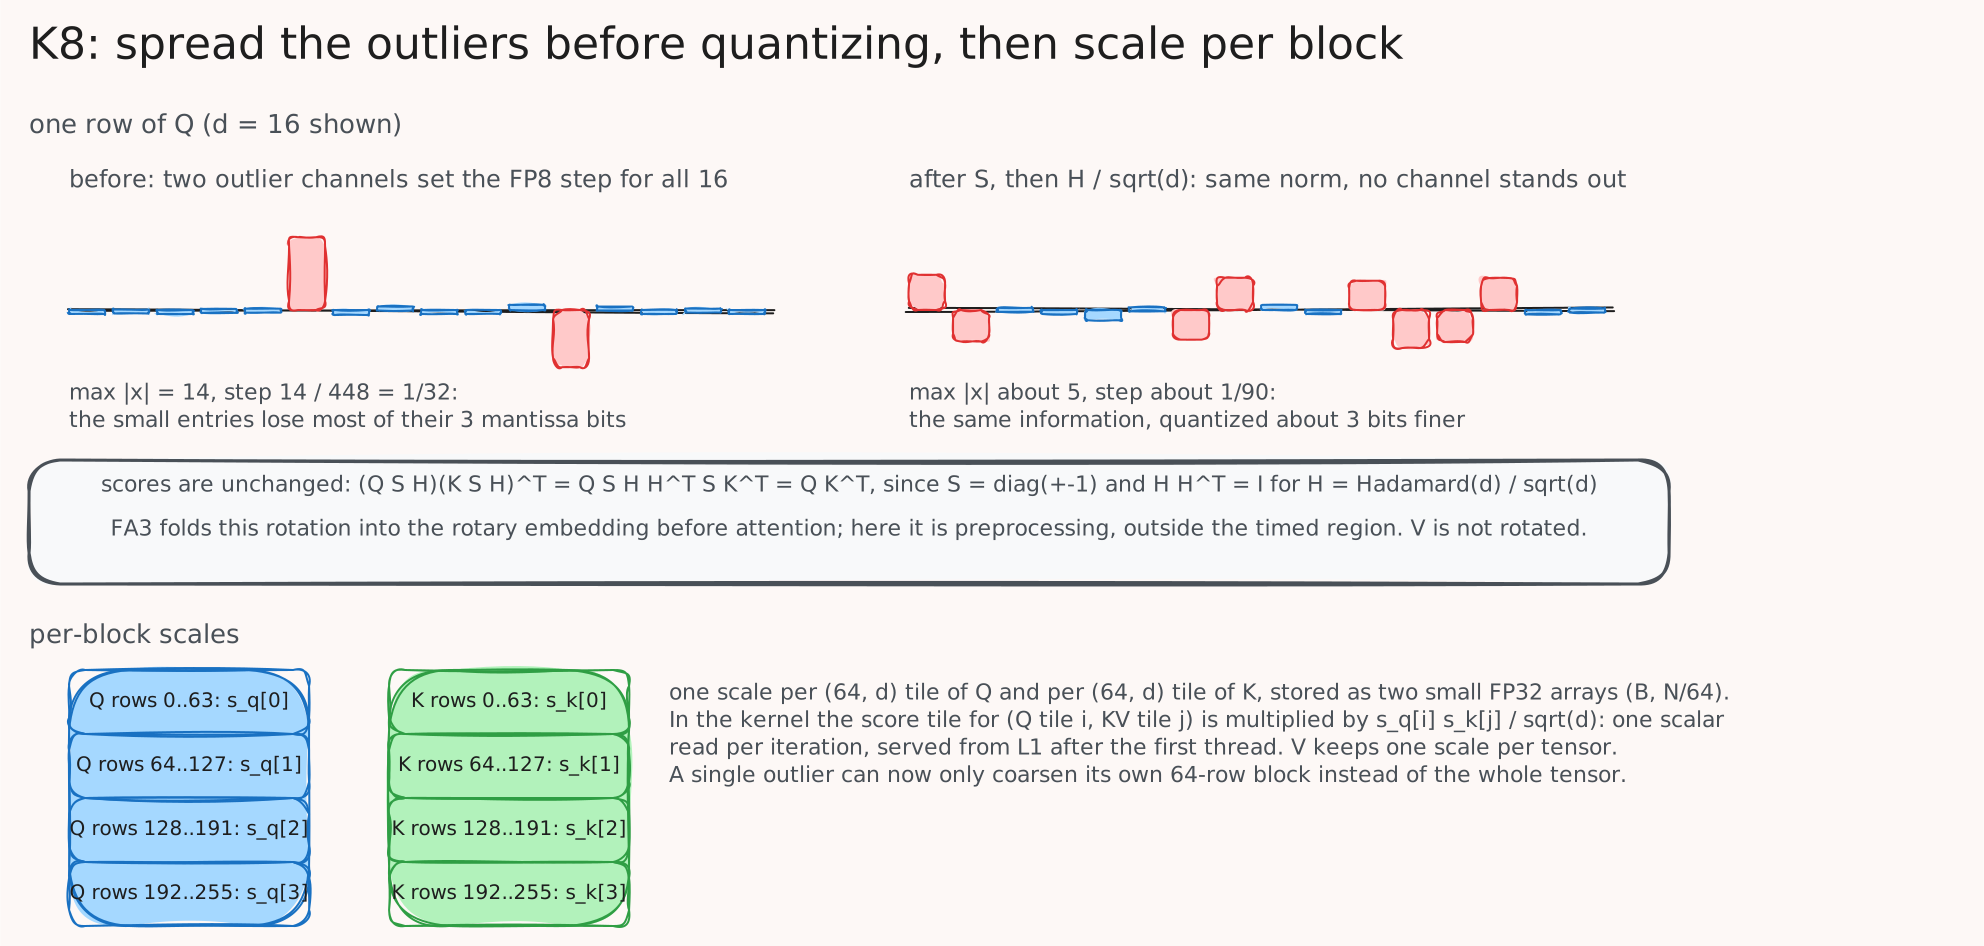
What changed from K7
Kernel: kernels/k8.py, which is the K7 class with per-block scales switched on; the rotation and the block quantization are in utils.py. The scale plumbing is in the CuTe post under block scales.
- Preprocessing, not timed. Q and K are rotated and quantized per block in PyTorch before the kernel runs; V keeps its per-tensor scale as in K7. FA3 folds the rotation into the rotary embedding that precedes attention, so in a model it costs nothing extra; here it is a separate step and is kept out of the measured time, which is stated rather than hidden.
- In the kernel: one multiply changes. The score dequantization factor becomes \(s_q[i]\, s_k[j] / \sqrt{d}\): the Q tile’s scale is read once per consumer, the K tile’s scale once per iteration from a \((B, N / 64)\) FP32 array, a single scalar per iteration served from L1 after the first thread’s miss. Everything else is K7.
Numbers
Throughput is K7 within noise: at 16k, 326 vs 347 TFLOPS at \(d = 64\) and 596 vs 577 at \(d = 128\), a few percent either way, which is the spread between runs of these measurements.
The point of K8 is error. Against exact FP32 attention on the unquantized inputs, on three data sets at \(d = 128\), non causal:
| data | K6 BF16 | K7 FP8 per-tensor | K8 FP8 rotated, block scales |
|---|---|---|---|
| uniform, \(N = 16384\), RMSE | 0.00005 | 0.0013 | 0.0014 |
| sharp attention, \(N = 4096\), RMSE | 0.00088 | 0.046 | 0.049 |
| outliers, \(N = 16384\), RMSE | 0.0014 | 0.50 | 0.18 |
| outliers, \(N = 16384\), max error | 0.0067 | 3.89 | 2.97 |
Over all twelve outlier configurations (both head dimensions, causal on and off, three sequence lengths) K8’s RMSE is 2.2x to 3x below K7’s.
Notes
- Uniform data hides the problem and sharp data does not need the fix. On uniform inputs there are no outliers, and both FP8 kernels sit near \(10^{-3}\), the e4m3 rounding of the inputs with nothing to amplify it. On sharp attention the error is dominated by the e4m3 rounding of \(P\) itself, which the rotation does not touch, so K7 and K8 are the same. The outlier set is the case the method exists for, and there it halves to thirds the error.
-
The worst element stays bad. With a few channels sixteen times larger than the rest, scores are in the hundreds and attention is one-hot. A relative error of a few percent in a score of that size can reorder two keys, and when it does, the output takes the wrong value row entirely; the maximum error of 3 to 4 is a full $$ V $$ swap. Block scales and the rotation make it rarer, which is what the RMSE shows, not impossible. That is the limit of three mantissa bits, and it is why FA3 reports FP8 error as an average. - The scale read is free. One FP32 per iteration, same address for all 128 threads of a warpgroup, against 8 WGMMA instructions and a few hundred FP32 operations per thread per tile. The differences to K7 are a few percent in both directions, which is the spread between runs of these measurements.
References
- FlashAttention-3 paper, section 3.3, block quantization and incoherent processing, and table 3
- QuIP, Chee et al. for incoherent processing with random sign and Hadamard rotations
Results
Everything in one place. All numbers are from the same node and the same harness: H100 SXM 80 GB at its 700 W power limit, nvidia-cutlass-dsl 4.5.1, 30 timed iterations after 10 warmup, FLOPs credited as \(4 B N^2 H d\) and halved for causal. The run ids are the JSON files under results/ in the repo; the library comparison is results/headline/.
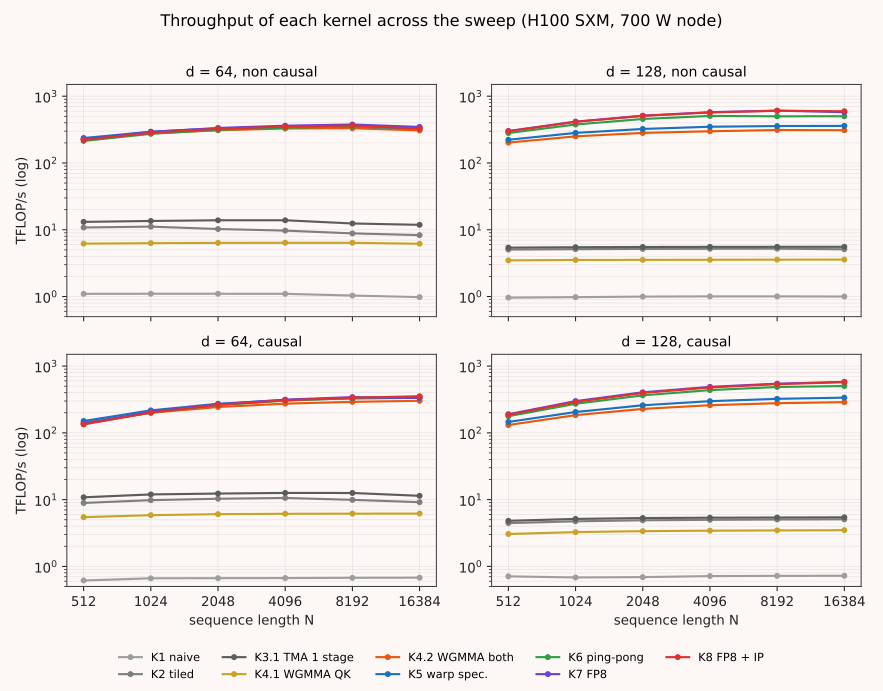
Three things to read off the sweep. The first three kernels are flat in \(N\) because nothing in them reuses a loaded byte more than tiling already does, and their height is set by the FP32 pipes and the register allocator. The jump to K4.2 is the tensor cores; everything above it is scheduling. And the FP8 kernels and the ping-pong kernel keep gaining with \(N\) while the single-consumer kernels flatten by 4k: with two consumers and 5 slots in flight, the per-CTA fixed costs (Q load, pipeline fill, epilogue) are amortized over more tiles, and at \(N = 512\) a CTA only has 8 tiles to amortize them over.
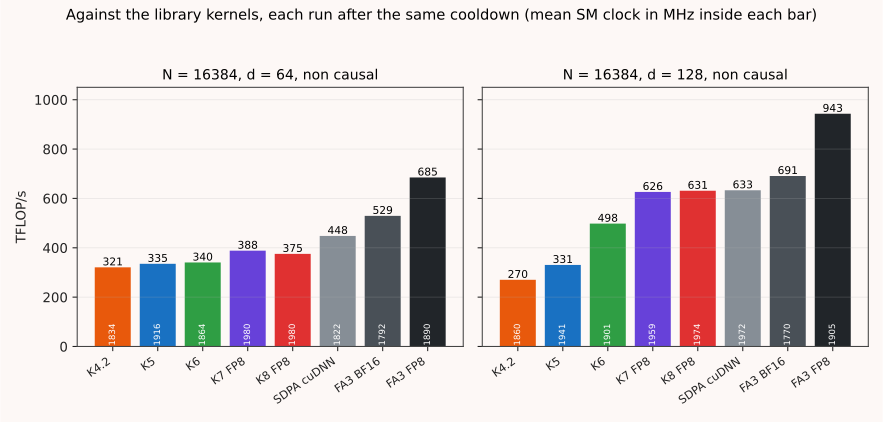
The library comparison has to be run with care on this node, and the first attempt showed why. Measured at the end of the long sweep, with the GPU at 85 C, FlashAttention-3 BF16 came out at 423 TFLOP/s at \(d = 128\), below K6, which is not a result anyone should believe: the FA3 paper reports up to 740 TFLOP/s for its BF16 forward pass. Run again with the same cooldown before every kernel, FA3 BF16 is at 691 and its FP8 kernel at 943, cuDNN’s BF16 kernel at 633, and the ordering is the one the code predicts. The eight runs, with the mean SM clock the sampler saw while each one ran:
| Kernel | \(d = 64\) TFLOPS | SM clock | \(d = 128\) TFLOPS | SM clock |
|---|---|---|---|---|
| K4.2 | 321 | 1834 MHz | 270 | 1860 MHz |
| K5 | 335 | 1916 MHz | 331 | 1941 MHz |
| K6 | 340 | 1864 MHz | 498 | 1901 MHz |
| K7 FP8 | 388 | 1980 MHz | 626 | 1959 MHz |
| K8 FP8 | 375 | 1980 MHz | 631 | 1974 MHz |
| SDPA, cuDNN backend, BF16 | 448 | 1822 MHz | 633 | 1972 MHz |
| FlashAttention-3 BF16 | 529 | 1792 MHz | 691 | 1770 MHz |
| FlashAttention-3 FP8 | 685 | 1890 MHz | 943 | 1905 MHz |
Read across: K8 reaches cuDNN’s BF16 kernel and sits at two thirds of FA3’s FP8 kernel at \(d = 128\); at \(d = 64\) the gap is wider, 375 against 685, because the ping-pong overlap that carries the \(d = 128\) case has little to work with at the small head dimension, as the K6 section showed. FA3 BF16 at 691 is 39 percent ahead of K6. What FA3 adds that this worklog does not have: \(128 \times d\) query tiles, so each warpgroup carries twice the output per thread and the softmax is a smaller share of the tile; pipelining inside each consumer warpgroup, so the softmax of tile \(j\) overlaps the \(QK^\top\) of tile \(j + 1\) even with one consumer; and an in-kernel transpose of V for FP8. Those are the next three kernels, in that order.
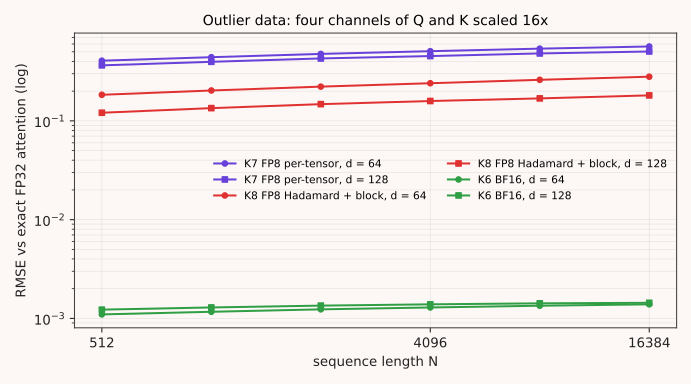
The numbers at \(N = 16384\), which is where the kernels have amortized their fixed costs:
| Kernel | \(d = 64\) | \(d = 128\) | \(d = 64\) causal | \(d = 128\) causal |
|---|---|---|---|---|
| K1 naive, materialized S | 1.0 | 1.0 | 0.7 | 0.7 |
| K2 tiled online softmax | 8.3 | 5.1 | 9.2 | 5.1 |
| K3.1 TMA, 1 stage | 11.8 | 5.6 | 11.4 | 5.4 |
| K3.3 TMA, 5 stages | 4.9 | 4.8 | 5.2 | 4.9 |
| K4.1 WGMMA for QK only | 6.2 | 3.6 | 6.2 | 3.5 |
| K4.2 WGMMA for both, P in registers | 308 | 310 | 302 | 288 |
| K5 warp specialization | 328 | 360 | 335 | 337 |
| K6 ping-pong | 334 | 501 | 347 | 502 |
| K7 FP8 per-tensor scales | 347 | 577 | 333 | 581 |
| K8 FP8, Hadamard, block scales | 326 | 596 | 353 | 574 |
Wrapping up
Eight kernels, one algorithm. K1 to K3 are the algorithm finding its shape: never materialize \(S\), keep the running state per row, let one thread issue the loads. From K4.2 on the kernel is the one FA3 describes, and each step after it is about keeping two kinds of hardware busy at the same time: the tensor cores and everything else. The numbers say how much each step is worth on this node, and the honest ones are worth stating plainly. Warp specialization alone is 6 to 16 percent. Ping-pong is 39 percent at \(d = 128\) and 2 percent at \(d = 64\), because the overlap window is the other consumer’s matmul and at the small head dimension the softmax is longer than it. FP8 is 15 percent, not 2x, for the same reason. The rotation and block scales cost nothing and cut the FP8 error by two to three times where it matters.
Some things I would not have believed without measuring them. A deeper TMA ring made a scalar kernel slower, and the compiled binary said why: spills. An unrolled loop of 16 iterations made K2 2.3x slower, and the binary said why again. The FP8 exchange was “known” to be harmful from a test that could not see it, and the sharp-attention test turned that around in one run. If there is one method in this worklog, it is that: for every claim, a number from this node, and for every surprising number, the cubin or a second data set.
What this worklog stops short of, in the order I would do them: pipelining inside each consumer warpgroup so the \(d = 64\) case overlaps too (FA3’s algorithm 2); \(128 \times d\) query tiles with the register budget that implies; an in-kernel transpose of V for FP8; the backward pass; and split-KV decoding for short query counts. The repo is at FlashAttention3, every number here is reproducible with one command per kernel, and the CuTe post has the primitives if the code reads opaque.
If you find a mistake anywhere in here, please let me know and I’ll fix it.
References